Most internet users interact with search engines as if conversing with an intuitive digital oracle, expecting algorithms to decipher ambiguous intent through natural language. For professional investigators and intelligence analysts, however, effective retrieval relies on a strictly mechanical reality: web search does not browse live websites in real time, but scans pre-compiled, tokenized inverted indexes constructed by automated crawlers. Mastering professional internet research requires deconstructing how crawlers parse HTML document trees, strip away decorative styling, catalog semantic containers, and mirror raw source code into Search Engine Result Page (SERP) snippets.
The Webpage Triptych: How Document Structure Dictates Discovery
Every web document is organized into a rigid tripartite hierarchy. While visual browsers render colors, typography, responsive grid layouts, and multimedia player widgets, an automated search engine crawler parses only the raw HyperText Markup Language (HTML). Understanding this architectural division enables researchers to anticipate exactly which parts of a target document are indexed, weighted, or ignored:
- The Header (The Invisible Brain): Encapsulated within the
<head>element, this zone is completely invisible to everyday visual readers. It contains crucial discovery metadata: the canonical document<title>, character set encodings, meta descriptions, open graph social protocols, and indexing directives (such asrobotsorcanonicalURLs). Automated spiders prioritize this section to establish primary topical relevance. - The Body (The Semantic Core): Enclosed by
<body>tags, this layer houses the substantive narrative text, structural heading hierarchies (<h1>through<h6>), tabular datasets, lists, and hyperlinks. Crawlers evaluate container weight: a term positioned within an<h1>element carries exponentially greater indexing authority than an identical term buried inside a deeply nested paragraph. - The Footer (The Structural Anchor): Resting at the base of the document, the footer supplies organizational provenance, corporate governance details, legal registrations, sitemaps, and network links. While rarely holding primary narrative evidence, footers serve as essential verification anchors for discovering corporate affiliations and parent entities.
The Ingestion Engine: How Spiders Crawl, Strip, and Index the Web
To grasp why certain documents appear at the top of search results while others remain completely obscured, analysts must follow the three-stage mechanical lifecycle that every indexed webpage undergoes:
1. The Client-Server Handshake & DNS Resolution
When an automated crawler (such as Googlebot or Bingbot) discovers a hyperlink, it initiates an HTTP/S request across the network. The Uniform Resource Locator (URL) is resolved through Domain Name System (DNS) lookups into an IP address, followed by folder path traversal to request the specific resource file hosted on the target server. If the server delivers a status 200 OK, the crawler pulls down the raw text payload.
2. The Stripping Process
Modern webpages are bloated with Cascading Style Sheets (CSS), client-side JavaScript libraries, responsive container wrappers, and decorative assets. Search crawlers do not spend computational cycles evaluating aesthetic design; they execute a ruthless stripping procedure. Visual styling is discarded, leaving only clean text strings, structural tags, and internal/external hyperlink matrices. What remains is a pure structural skeletal representation of the webpage.
3. Tokenization & Inverted Index Construction
The stripped text is parsed by tokenization algorithms that remove common stop words (e.g., “the”, “is”, “at”), calculate term frequency-inverse document frequency (TF-IDF), evaluate semantic entity relationships, and catalog anchor text links. This processed data is stored in massive, distributed inverted indexes—repositories that map specific keywords directly to the unique Document IDs where they appear.
| Processing Stage | Input Data | System Action | Investigative Significance |
|---|---|---|---|
| 1. Discovery & Fetch | Hyperlinks & Sitemaps | DNS resolution, HTTP request, robots.txt compliance check | Unlinked or orphaned pages cannot be discovered without direct URL submission or sitemaps. |
| 2. Stripping Engine | Full HTML, CSS, Scripts | Extracts raw markup; strips stylesheets, inline scripts, visual frames | Visual prominence (font size, bold colors) is ignored in favor of semantic container tags. |
| 3. Content Ingestion | Parsed Text & Tags | Tokenization, stop-word filtering, term weighting, link graph construction | Container hierarchy determines relevance score: <title> > <h1> > <h2> > <p>. |
| 4. Inverted Indexing | Weighted Tokens | Maps keyword tokens to document addresses in distributed repositories | Queries match against pre-compiled index entries, never against the live, dynamic website. |
The Crawler’s Blind Spots: What Automation Fails to Ingest
Because search engines rely on automated parsing pipelines, their visibility into the web is constrained by significant mechanical blind spots. Understanding these failure points reveals where traditional search engines fail and where specialized deep-web investigative methodologies must take over:
- Missing Image Alt Text: While modern multimodal AI models can analyze visual images, standard web search crawlers still rely heavily on text attributes. An informational chart or evidence document embedded as a JPEG or PNG without an explicit
alt="..."attribute is virtually invisible to indexers. - Dynamic JavaScript & Client-Side Hydration: Heavy single-page applications (SPAs) that require user interaction—such as clicking tabs, selecting drop-downs, or submitting form queries—often fail to render before crawler timeouts expire. If content requires user-triggered JavaScript execution to become visible in the DOM, search crawlers frequently miss it entirely.
- Gated Databases & Ephemeral Content: Content hidden behind authentication walls, session tokens, dynamic database query forms, or CAPTCHA defenses cannot be traversed by web spiders. This vast expanse constitutes the Deep Web, accessible only through direct endpoint queries and specialized investigative tools.
Anatomy of a Search Result: Mapping HTML Directly to the SERP
Every standard Search Engine Result Page snippet is an x-ray projection of the underlying source code. By analyzing snippet structure, an investigator can instantly diagnose the architecture of the source document:
| SERP Snippet Element | Underlying HTML Container | Search Engine Function | Targeting Operator |
|---|---|---|---|
| Clickable Headline | <title>...</title> (or primary <h1>) |
Establishes primary topical authority and clickable link to destination | intitle: / allintitle: |
| Breadcrumb / URL Path | Protocol + Domain + Subfolder Directory | Indicates structural location, document format, and repository branch | inurl: / allinurl: |
| Contextual Snippet Excerpt | <meta name="description"> or matching <p> body text |
Provides summary preview containing highlighted query search terms | intext: / allintext: |
Targeting HTML Containers with Precision Search Operators
Casual searching relies on keyword scatter, hoping the algorithm prioritizes the intended context. In contrast, advanced query engineering commands the search engine to examine specific container tags within the index. By constraining queries to targeted HTML elements, researchers filter out millions of commercial matching pages to isolate definitive primary sources:
| Operator Syntax | Target Container | Operational Mechanism | Investigative Use Case |
|---|---|---|---|
intitle:"keyword" |
<title> tag |
Matches pages where the primary document headline contains the exact phrase | Isolating definitive policy briefs or case studies where the topic is the core thesis. |
allintitle:term1 term2 |
<title> tag |
Demands that every specified term appear inside the title tag | Eliminating secondary commentary to locate specific legal or academic filings. |
inurl:directory/path |
URL / Folder structure | Restricts retrieval to documents housed in specific directory paths | Uncovering hidden file repositories, such as inurl:wp-content/uploads or inurl:reports. |
allinurl:terms |
URL string | Forces all query terms to exist within the address stem | Locating regional or language-specific mirrors across global corporate domains. |
intext:"verbatim quote" |
<body>, <p>, <td> |
Bypasses title and URL to search strictly inside substantive body paragraphs | Tracking leaked statements, specialized technical jargon, or specific financial figures. |
filetype:pdf / ext:csv |
MIME type / Extension | Filters the index strictly for specific file formats and binaries | Extracting raw spreadsheets, government audits, or academic slide presentations. |
Video Masterclass: Precision URL and Directory Interrogation
To see these mechanics deployed in live investigative scenarios, watch this technical breakdown from the AOFIRS Web Search Skills Series demonstrating advanced directory and address-stem interrogation techniques using inurl: and allinurl::
Master Advanced Information Retrieval with CIRS™
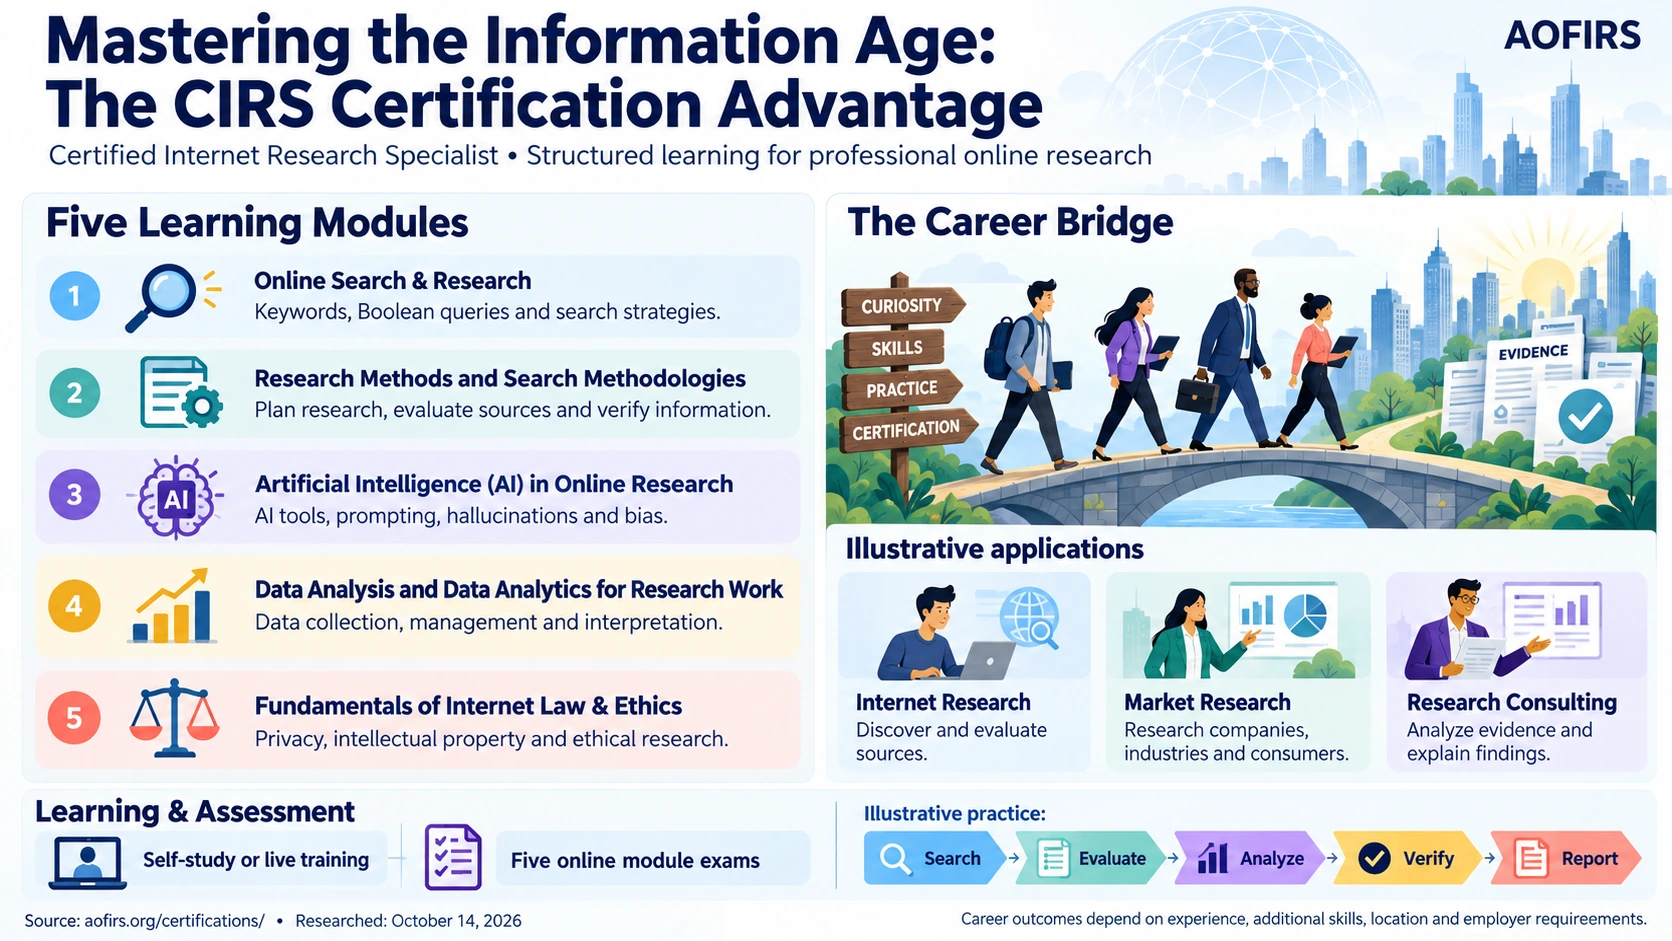
Move beyond automated search engines and surface-level results. The Certified Information Research Specialist (CIRS™) Program provides comprehensive, professional training in advanced query architecture, open-source intelligence (OSINT), and multi-engine verification frameworks.
Related AOFIRS Publications & Research Guides
Deepen your information retrieval capabilities with these foundational research guides and technical analyses:
- The Search Architect’s Toolkit: Advanced Search Methods & Precision Query Engineering – Architectural methodologies for cross-engine retrieval and deep-web extraction.
- Master Google Search: From Keywords to Precision Queries – Practical operational blueprints for deploying Boolean logic and structural operators.
- The Researcher’s Journey: From Raw Data to Actionable Insight – The complete four-tier analytics maturity model and five-stage data refinement pipeline.
- The Architect of Truth: Training the Augmented Researcher – The 2026 framework for orchestrating AI tools while defending evidence integrity.
- The New Research Landscape: Navigating AI Synthesis and Web Search – Comparing generative synthesis models against empirical web indexing.
Frequently Asked Questions (FAQs)
Why does a search engine query a pre-compiled index rather than the live Internet?
The World Wide Web contains hundreds of billions of dynamic pages. Scanning the live web in real time during a query would demand unfeasible network bandwidth and introduce latency of several minutes per search. Instead, search engines deploy automated crawlers to crawl, strip, tokenize, and pre-index documents into massive distributed databases. When you submit a search query, you are interrogating this pre-compiled inverted index in milliseconds, not the live web.
What is the operational difference between the intitle: and intext: operators?
The intitle: operator restricts search engine retrieval exclusively to the contents of the HTML <title> element, isolating documents where your search query represents the core subject or headline. Conversely, intext: instructs the engine to bypass metadata and titles to search exclusively within the narrative <body> tags (such as <p> and <li>), ideal for discovering passing mentions, buried figures, or exact quotations.
Why do search engine crawlers frequently miss client-side JavaScript content?
Crawlers prioritize computational efficiency and rapid throughput. While search engines can execute basic JavaScript, pages that depend on complex Single Page Application (SPA) hydration, dynamic user interactions (such as selecting options from drop-down menus or clicking accordion tabs), or client-side AJAX requests often fail to render completely before the crawler’s execution timeout expires, causing the underlying text to remain unindexed.
How does Google handle long, truncated <title> tags when executing an intitle: query?
Although search engines visually truncate long title tags in SERP snippets (typically after approximately 60 characters or 600 pixels of display width), the complete text of the <title> element is preserved inside the inverted index. As a result, an intitle: search will successfully locate and match keywords located even at the very end of an extended, truncated title tag.
How does understanding HTML document structure improve evidence authentication?
Inspecting the raw HTML source code allows investigators to look beyond visual layout. Analysts can inspect publication timestamps in metadata tags, verify canonical author and organization IDs, identify tracking scripts, confirm whether text was generated dynamically or hardcoded, and detect cloaking techniques where different content is served to crawlers than to visual human visitors.