Search engines shape how people discover information, compare evidence and make decisions. Yet researchers rarely see how commercial ranking algorithms work or why particular sources appear above others.
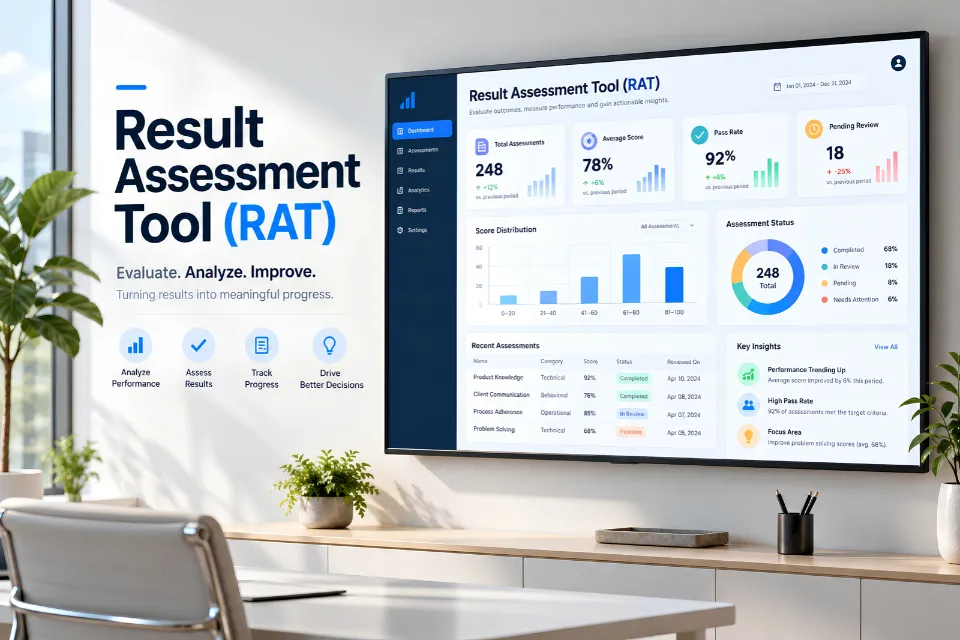
The Result Assessment Tool (RAT) helps address this problem. It provides a structured way to collect search results, examine their characteristics and assess their relevance through automated analysis and human evaluation.
For researchers investigating search quality, information diversity or AI-generated answers, RAT offers an open-source framework for conducting more systematic studies.
This guide explains what RAT does, how to use it and which methodological limitations researchers should consider in 2026.
What Is the Result Assessment Tool (RAT)?
The Result Assessment Tool (RAT) is free, open-source research software designed to collect, analyze and evaluate results from search engines and other information retrieval systems.
Developed by researchers associated with the Hamburg University of Applied Sciences in Germany, RAT supports studies involving commercial search engines, library discovery systems and other web-based information services.
Its development has received support from the German Research Foundation (DFG).
RAT is particularly useful for investigating questions such as:
- Do different search engines return equally relevant information?
- Which websites dominate the first page of search results?
- How diverse are the sources presented for a particular topic?
- How do search engines represent commercial, educational or public-interest information?
- How do AI-generated answers differ from conventional search results?
Unlike commercial rank-tracking platforms, RAT is primarily a research instrument, not a tool designed to increase website rankings.
Its purpose is to help researchers gather evidence about search systems and evaluate that evidence using documented methods.
The 2025 PeerJ Computer Science paper, Result Assessment Tool (RAT): Empowering Search Engine Data Analysis, describes its architecture and applications in information retrieval research. Read the 2025 research paper.
How Does RAT Work?
RAT supports four connected research activities:
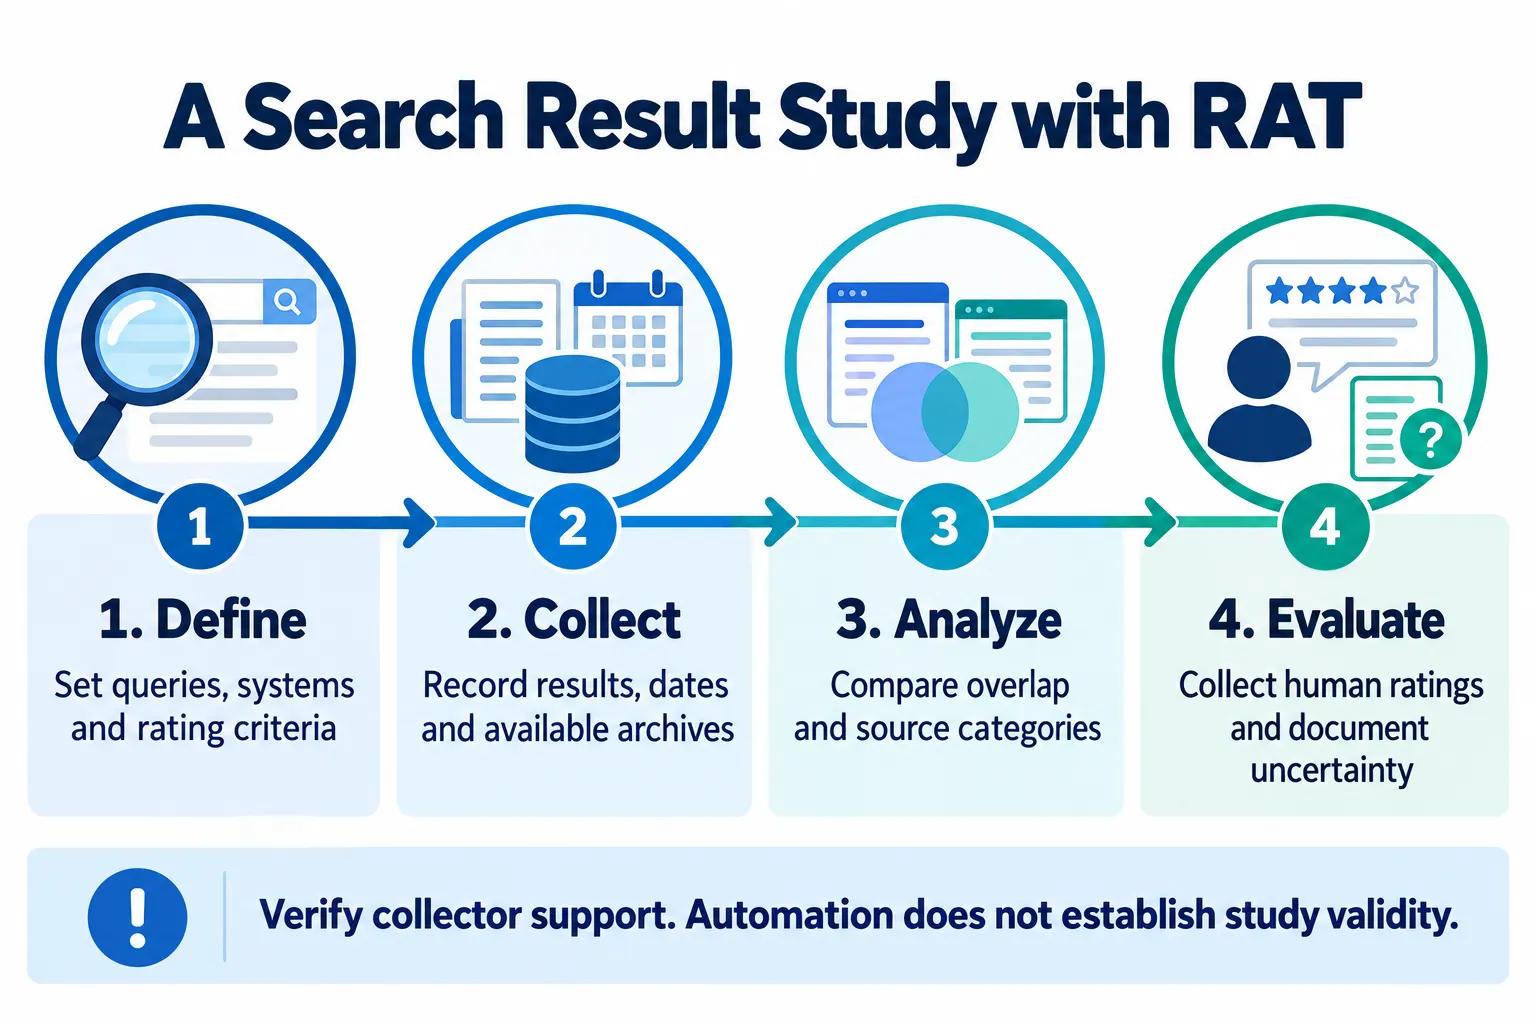
These stages help researchers move from a research question to a documented assessment of search results.
1. Define the Research Study
Every reliable search engine evaluation begins with a specific question.
Researchers use RAT’s Study Designer to establish the study parameters, including search queries, collection requirements and evaluation criteria.
For example, a study might investigate whether Google and Bing provide similar sources for questions about renewable energy.
Researchers should establish:
- The search engines being compared.
- The queries included in the study.
- The location and language of searching.
- The collection dates.
- The number and types of results examined.
- The criteria used to judge relevance or quality.
RAT also documents a Query Sampler that can support systematic query selection using the Google Ads API.
A carefully selected query sample matters because conclusions based on a handful of convenient searches may not represent broader search behavior.
2. Collect Search Results
Once the study is configured, RAT’s collection modules retrieve search result information.
Depending on the configured collector and supported search system, data may include:
- Search queries and result positions.
- Page titles, URLs and snippets.
- Source-page content and HTML.
- Archived screenshots.
- Relevant metadata for subsequent analysis.
RAT uses automated collection methods, including Selenium WebDriver, to interact with web pages and retrieve content.
Archiving is important because search results and destination pages change. A result visible today may move, disappear or display different content tomorrow.
Recording the collection date and retaining available source material helps researchers explain what was actually observed.
Automated collection remains subject to platform restrictions, interface changes and technical failures.
3. Analyze Search Data
After collection, RAT supports automated examination of search result characteristics.
Its extensible classification framework allows researchers to apply analytical scripts to stored search data.
The academic documentation describes a pre-implemented SEO classifier that estimates whether webpage characteristics indicate search engine optimization.
This classification is not proof of ranking manipulation, spam or a Google penalty. It is a model-based assessment that requires interpretation and validation.
Researchers may also develop appropriate classifiers for other research questions, such as document categories or content characteristics.
Possible analytical activities include comparing result overlap, examining source distributions and investigating differences between search systems.
Any custom classifier should be tested for accuracy, bias and relevance to the study.
4. Evaluate Results Through Human Assessment
Automated measurements cannot fully explain whether information satisfies a person’s needs.
RAT therefore provides an Evaluation View where study participants, sometimes called jurors, assess collected results.
The interface can present archived content alongside questionnaires containing rating scales, sliders or open-ended questions.
Researchers might ask participants:
- Does the result answer the search question?
- Is the content understandable?
- Does the source provide supporting evidence?
- How useful is the information for the intended task?
Using archived material helps participants assess the same version of a result.
Researchers should still consider differences in participant expertise, interpretation and judgment.
Where multiple assessors evaluate results, agreement measures can help identify inconsistent ratings.
Key RAT Features and Research Capabilities
RAT combines several research functions within a modular software environment.
| Component | Main function | Important limitation |
|---|---|---|
| Study Designer | Configures studies and query sets | Study quality depends on research design |
| Search Engine Scraper | Collects supported search results | Search interfaces and access restrictions change |
| Source Scraper | Retrieves linked webpage content | Some pages cannot be fully captured |
| Query Sampler | Supports systematic query selection | API access and query coverage may be limited |
| Classifier Framework | Supports automated analysis | Outputs depend on model quality |
| Evaluation View | Collects human assessments | Participant ratings may differ |
| Analyzer | Displays collection and assessment statistics | Statistics require methodological interpretation |
| Data Exporter | Exports research data in XLSX format | Exported data still require validation |
RAT’s architecture includes two principal applications: a Flask-based frontend and a Python-based backend, connected through PostgreSQL.
The frontend manages study design and participant assessment. The backend performs collection and classification tasks.
This separation supports flexible research deployments, including self-hosted installations.
How to Use RAT for Search Engine Research
Researchers can begin with the hosted application or explore a self-hosted deployment.
Step 1: Access the Software
Visit the official RAT website and open the hosted research application.
The project also publishes RAT source code on GitHub.
The hosted version provides an accessible starting point. Self-hosting offers greater control over configuration but requires technical knowledge.
Step 2: Create a Research Study
Define a clear question and prepare a query list.
Select the search systems and collection settings supported by the available configuration.
Keep a record of the research scope, sampling method and collection conditions.
Planning Prompts and a Rating Example
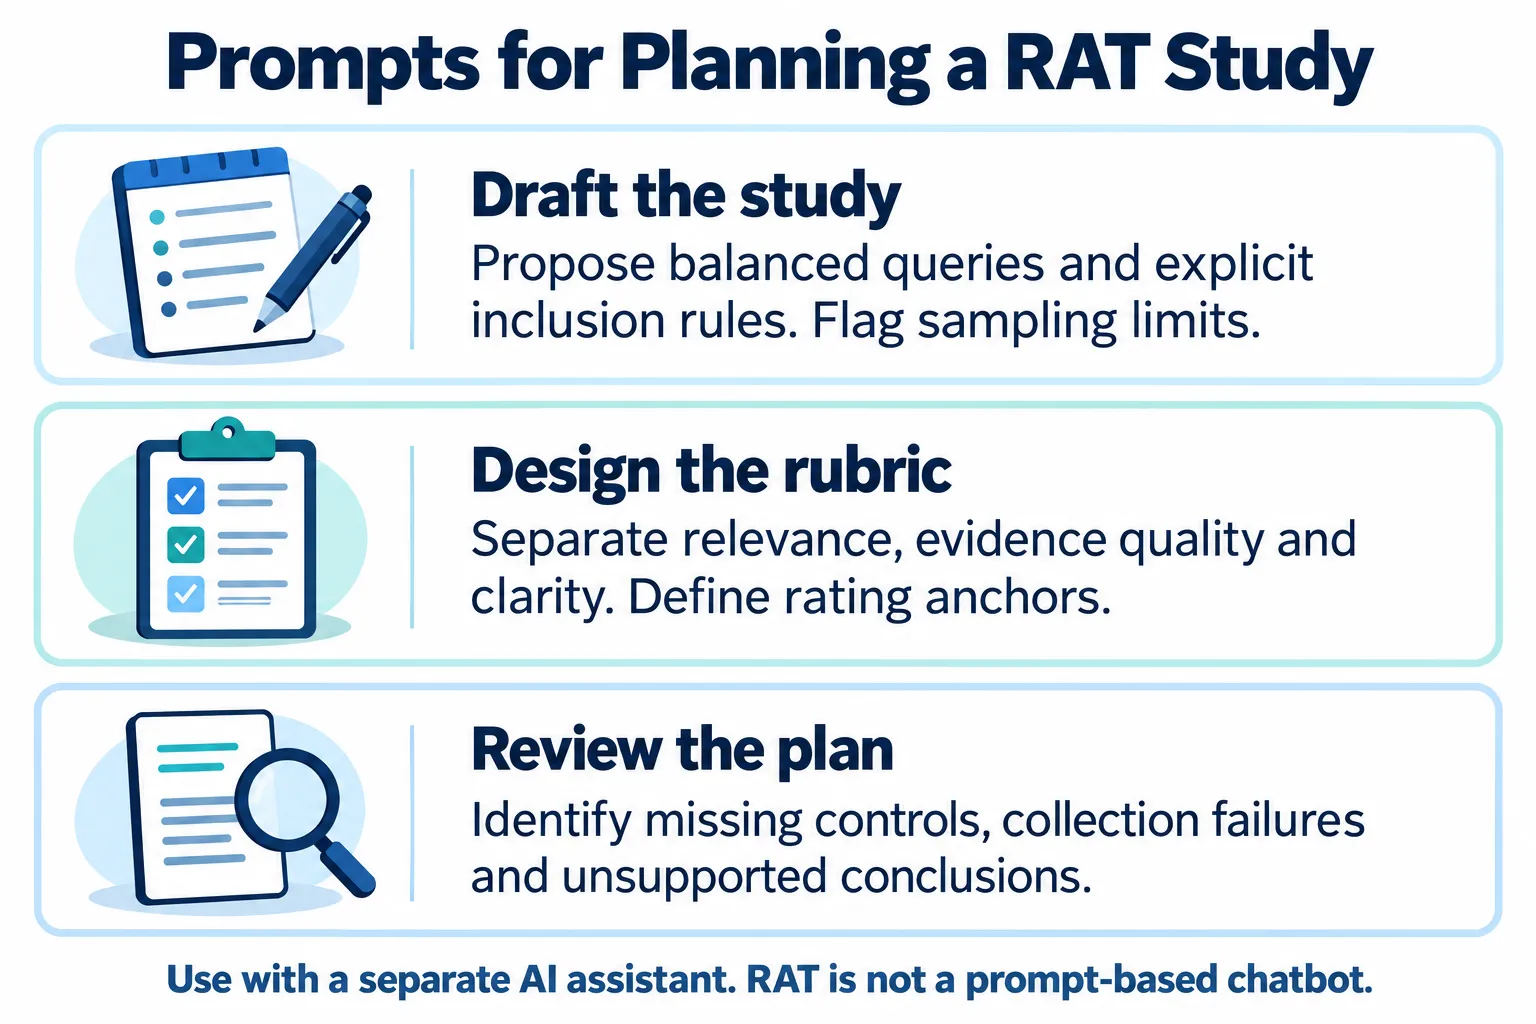
Draft a study comparing two search engines for a defined information need. Propose balanced queries and explicit inclusion rules. Separate relevance, evidence quality and clarity. Identify missing controls and assumptions. Do not invent collected results.
Use this with a separate AI assistant, then validate the plan against RAT’s current configuration. A draft relevance scale might be 0 = does not address the question, 1 = partly addresses it, and 2 = directly addresses it. Record inaccessible or unassessable content separately from irrelevant content. Pilot the rubric with assessors before using it in the study.
Step 3: Collect and Assess Results
Run the configured collection process and inspect the resulting dataset.
Check whether queries completed successfully, whether content was captured and whether important results are missing.
Apply appropriate analysis methods and configure human assessment when the research question requires judgment.
Step 4: Export and Interpret Findings
RAT’s Data Exporter supports downloading collected research information in XLSX format.
Researchers can use spreadsheets or statistical software for additional analysis.
Document any missing data, collection errors and unexpected results rather than excluding them without explanation.
For installation requirements, consult the RAT knowledge base and repository documentation. Technical dependencies and setup procedures may change between releases.
Practical Example: Comparing Google and Bing Results
Suppose researchers want to understand how Google and Bing present information about childhood vaccination.
This illustrative study could follow four stages.
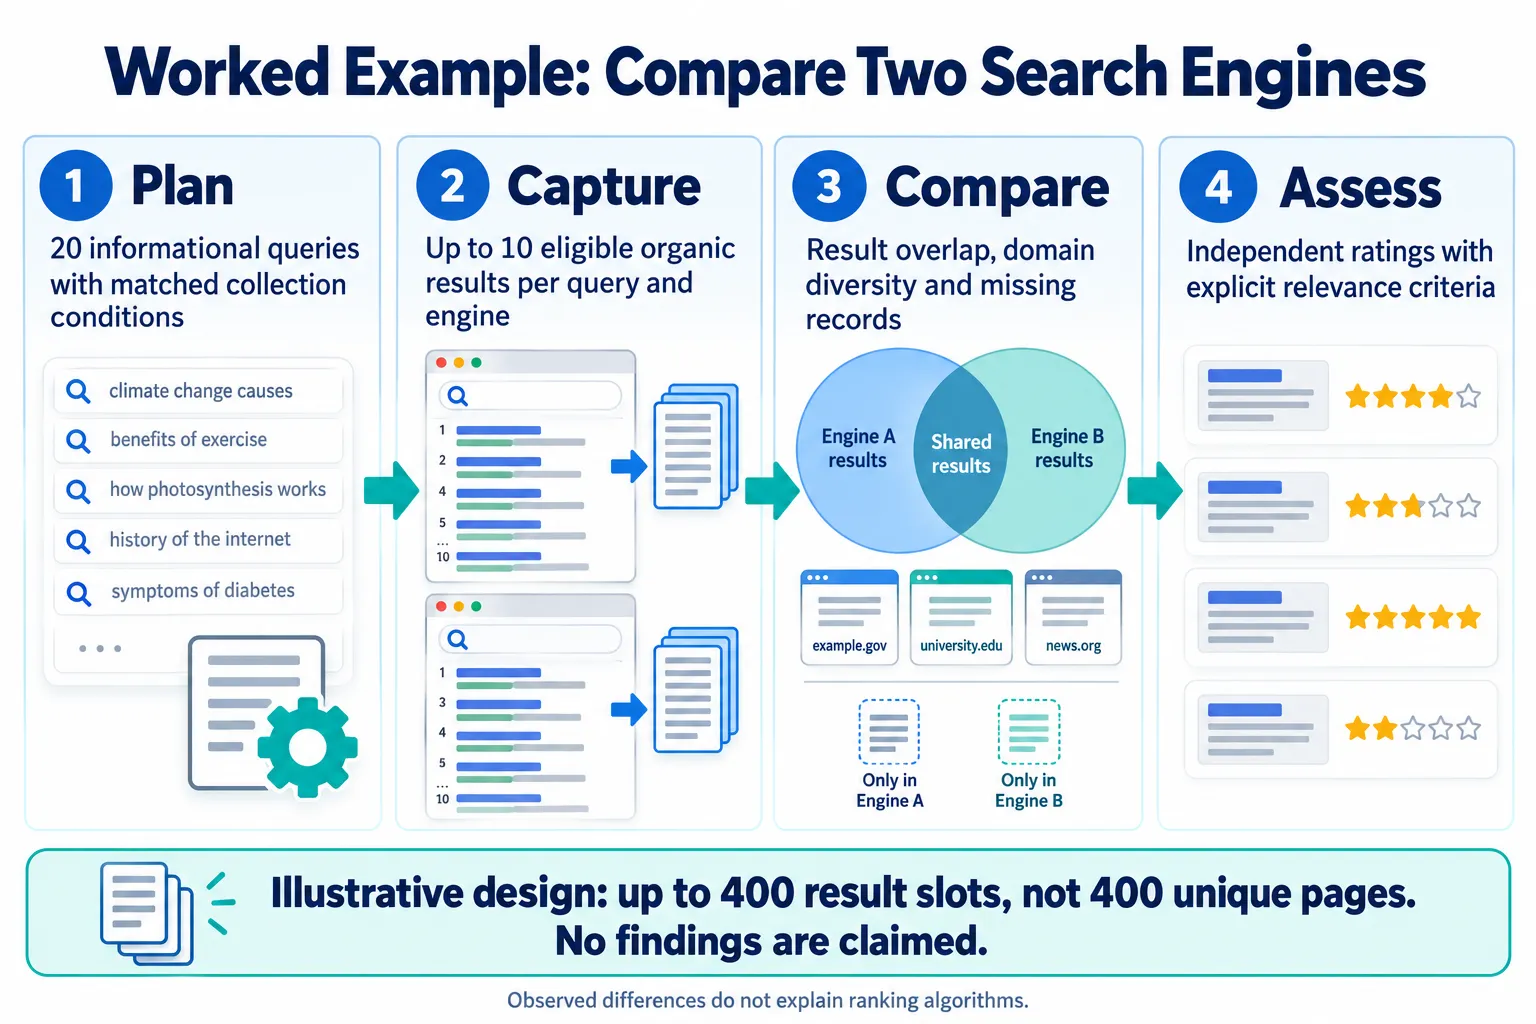
At most, this design has 20 × 2 × 10 = 400 result slots. Repeated URLs, missing results and failed captures affect the actual dataset. Report both result-slot counts and deduplicated page or domain counts, using an explicit URL normalization rule.
Define: Select 20 informational queries, establish consistent collection conditions and define relevance criteria.
Collect: Retrieve the first ten eligible organic results for each query from both search engines, where technically permitted. Record rankings, URLs and collection times.
Analyze: Compare repeated domains, result overlap and the proportions of government, academic, healthcare and commercial sources.
Evaluate: Ask independent assessors to rate the usefulness and evidence quality of a sample of results.
The study could reveal differences in source visibility or relevance assessments.
However, differences between the collected results would not establish why a search engine ranked particular sources or prove that one system is inherently more trustworthy.
A sound report would also describe query sampling, missing results, assessor agreement and geographic limitations.
RAT and AI-Powered Search in 2026
Generative AI is changing how people encounter information.
Traditional search engines generally present ranked links, while AI-powered systems may generate direct answers supported by citations or source references.
Google AI Overviews and AI Mode, ChatGPT Search, Microsoft Copilot and Perplexity illustrate different approaches to AI-assisted information discovery.
These developments introduce new research questions:
- Which sources influence or appear in AI-generated answers?
- Are claims supported by the referenced material?
- Do different systems present consistent answers?
- How do answers vary across prompts, locations or sessions?
- Does an AI-generated summary omit relevant perspectives?
Can RAT Collect AI-Generated Answers?
The March 2026 ACM CHIIR publication documents RAT’s ability to collect AI-generated content, including Google AI Overviews and answers from chatbots such as ChatGPT. Read the 2026 CHIIR paper.
This is an important development because conventional search result studies do not fully capture generative answer experiences.
However, the documented support should not be interpreted as universal integration with every AI search platform.
Researchers must verify the availability and behavior of specific collection modules before designing their studies.
A browser extension intended to collect results through ordinary browser sessions was described in the March 2026 paper as being under development.
Why AI Search Evaluation Is More Difficult
AI answers introduce several additional measurement problems.
Answer variability: Similar prompts may produce different responses.
Citation reliability: A cited webpage may not support every associated claim.
Interface changes: Platforms regularly alter how answers and references are displayed.
Limited transparency: Researchers generally cannot inspect proprietary model weights, complete retrieval processes or internal ranking decisions.
Reproducibility: Capturing one answer does not guarantee that another researcher will receive the same output.
AI search assessment therefore requires careful prompt documentation, repeated observations where appropriate, source checking and human interpretation.
For a broader workflow, see the AI research guide.
Who Can Benefit From RAT?
RAT supports several professional research applications.
Academic researchers can compare retrieval effectiveness and investigate search engine behavior, provided their query samples support the conclusions drawn.
Librarians and information professionals can assess whether discovery systems return material relevant to users’ information needs.
Journalists and investigators can document the visibility of sources relating to public-interest topics. Collected rankings should not be treated as evidence of editorial intention.
SEO and digital research professionals can study search result composition, result overlap and source visibility without treating RAT as a replacement for analytics or rank-monitoring platforms.
Public policy researchers can examine information diversity, accessibility and potential disparities in search results.
AI researchers can investigate supported generative search outputs, citation patterns and differences between AI-generated answers.
These applications are most valuable when researchers define measurable criteria and acknowledge the limits of their data.
RAT Compared With Manual Search Result Evaluation
| Research activity | Manual approach | RAT-supported approach |
|---|---|---|
| Query collection | Search individually | Configure automated collection |
| Result recording | Copy URLs and notes | Store structured result data |
| Page preservation | Save files manually | Use supported archival modules |
| Classification | Review each item | Apply configured classifiers |
| Human assessment | Distribute separate questionnaires | Use an integrated evaluation interface |
| Data preparation | Compile spreadsheets manually | Export structured study data |
RAT can reduce repetitive research work, but automation does not automatically improve the validity of a study.
For small exploratory tasks, a carefully documented manual process may be sufficient.
Research Reliability, Limitations and Ethics
Reliable search research depends on more than collecting large datasets.
Search results vary according to location, language, timing, interface design and potentially personalization.
Automated scrapers may miss dynamically loaded content, encounter access restrictions or fail when websites change.
Classifier outputs can contain errors. Human assessors may disagree, particularly when criteria are ambiguous.
Researchers should record their methodology, inspect data completeness and distinguish observations from explanations.
Responsible data collection also requires attention to website policies, personal information, copyright and secure storage.
The availability of open-source collection software does not remove legal or ethical responsibilities.
Where studies involve human participants, researchers should consider informed consent, confidentiality and relevant institutional requirements.
Use the verification guide for source checking and evidence documentation.
Frequently Asked Questions
1. What is the Result Assessment Tool (RAT)?
RAT is open-source research software for studying results from search engines and other information retrieval systems. It brings together study design, data collection, automated classification and human evaluation to support structured investigations of retrieval quality, source diversity and search behavior.
2. Is RAT free and open source?
Yes. The official project describes RAT as free and open source. Researchers can access its web application or obtain the software through its public repositories. Self-hosting may involve infrastructure, administration and maintenance costs.
3. How does RAT collect search results?
RAT uses configurable collection modules, including browser automation, to retrieve search result metadata and relevant webpage content. Depending on the supported collector, the dataset may contain titles, URLs, snippets and archived documents. Collection success depends on platform accessibility and current software support.
4. Can RAT analyze Google AI Overviews and ChatGPT answers?
The 2026 ACM publication documents collection capabilities for Google AI Overviews and chatbot answers, including ChatGPT. Researchers should verify the relevant module’s current availability, configuration and limitations before assuming that a particular AI platform can be studied.
5. Does RAT require programming knowledge?
The hosted interface allows researchers to undertake core research activities without developing the software themselves. Advanced configuration, custom classifier development and self-hosted installation may require Python, database administration and web automation skills.
6. How is RAT different from commercial SEO tools?
Commercial SEO platforms generally concentrate on ranking visibility, website performance and marketing analysis. RAT focuses on research studies involving search results, including collection, classification and human assessment. Its purpose is methodological investigation rather than direct website optimization.
7. Can RAT determine whether search results are trustworthy?
RAT supports the collection of evidence and structured assessments, but it does not independently establish that every result is accurate or trustworthy. Credibility judgments require appropriate criteria, source verification and careful interpretation of automated and human evaluations.
8. What are RAT’s main limitations?
Its limitations include changing search interfaces, collection restrictions, incomplete archives, differences in location and personalization, and possible classification errors. Reproducibility also depends on documentation, stable research procedures and recognizing that live search systems continually change.
Conclusion
The Result Assessment Tool provides researchers with a practical framework for investigating what search systems display and how those results can be assessed. Its combination of automated collection, configurable analysis and human evaluation makes it useful for information retrieval studies, source diversity research and selected investigations of AI-powered search. As search interfaces evolve, the central research challenge remains the same: collect reliable evidence, evaluate it using transparent criteria and explain what the findings can and cannot establish. RAT supports that process, but sound research still depends on careful study design and informed human judgment.