Every search you run is a conversation with an index — a vast, pre-computed map of the web built long before you typed a single word. Understanding how search engines crawl, parse, and index webpages is what separates researchers who find evidence from those who merely find results. This technical training report deconstructs the search engine lifecycle, from the crawling of HTML structures to the indexing of metadata, and provides a professional framework for using advanced operators to bypass algorithmic noise and retrieve high-precision evidence.
From Address Bar to Answer: The Indexing Lifecycle
When you submit a query, the engine does not search the live web — it searches its index, a structured database built by crawlers that continuously fetch and parse billions of pages. Knowing what happens at each stage tells you exactly why some content is findable and some is invisible.
| Stage | What the Engine Does | What It Means for Researchers |
|---|---|---|
| Discovery | Crawlers follow links, sitemaps, and feeds to find new or updated URLs. | Pages with no inbound links or sitemap entry may never surface — check alternate discovery paths. |
| Crawling | The fetcher retrieves the raw HTML, resolves DNS, and honors robots.txt and crawl budgets. | Blocked or slow pages are skipped; use caches and archives when a source is unreachable. |
| Parsing & Rendering | The engine strips boilerplate, reads title tags, headings, meta data, and increasingly executes JavaScript. | Content locked behind scripts or logins may be indexed partially or not at all. |
| Indexing | Tokens are stored in an inverted index mapping terms to documents, alongside freshness and authority signals. | Exact-phrase and field-specific operators work because the index preserves word positions and zones. |
| Ranking & Serving | Query terms are matched against the index, scored, and returned as snippets. | Ranking is personalization-sensitive — verbatim and operator-driven queries cut through the noise. |
Querying the Index Like a Professional
Advanced operators are not tricks — they are direct instructions to the index. Each one constrains which field of a stored document your terms must match.
Field-Restricted Operators
intitle:/allintitle:— match terms in the page title, the strongest topical signal an author gives.inurl:/allinurl:— match terms in the URL path, exposing directory structures, file names, and parameter patterns.intext:— require terms in the body copy, filtering out navigational and boilerplate matches.site:— confine results to a domain or TLD, turning any website into a searchable database.filetype:— target indexed document formats (PDF, XLSX, PPTX, DOCX) where reports and datasets live.
Precision Modifiers
- Quotation marks force exact-phrase matching against the index’s positional data.
- The minus operator excludes documents containing a term — essential for disambiguating names and brands.
ORand parenthetical grouping widen recall without losing control of the query logic.- Date filters and
before:/after:constraints exploit the freshness timestamps stored at index time.
Why Pages Go Missing: Indexing Blind Spots
Professional researchers treat a null result as a hypothesis, not an answer. Common causes of invisibility include robots.txt exclusions, noindex directives, orphaned pages with no inbound links, JavaScript-dependent rendering, duplicate-content consolidation, and crawl-budget starvation on large sites. Each has a workaround: cached copies, the Wayback Machine, alternate indexes (Bing, DuckDuckGo, Yandex), and direct site-architecture mapping.
Watch: Google Advanced Search Tips & Tricks
This session from the AOFIRS Web Search Skills Series demonstrates the querying techniques above in live searches.
Master the Mechanics of Search — Get CIRS™ Certified
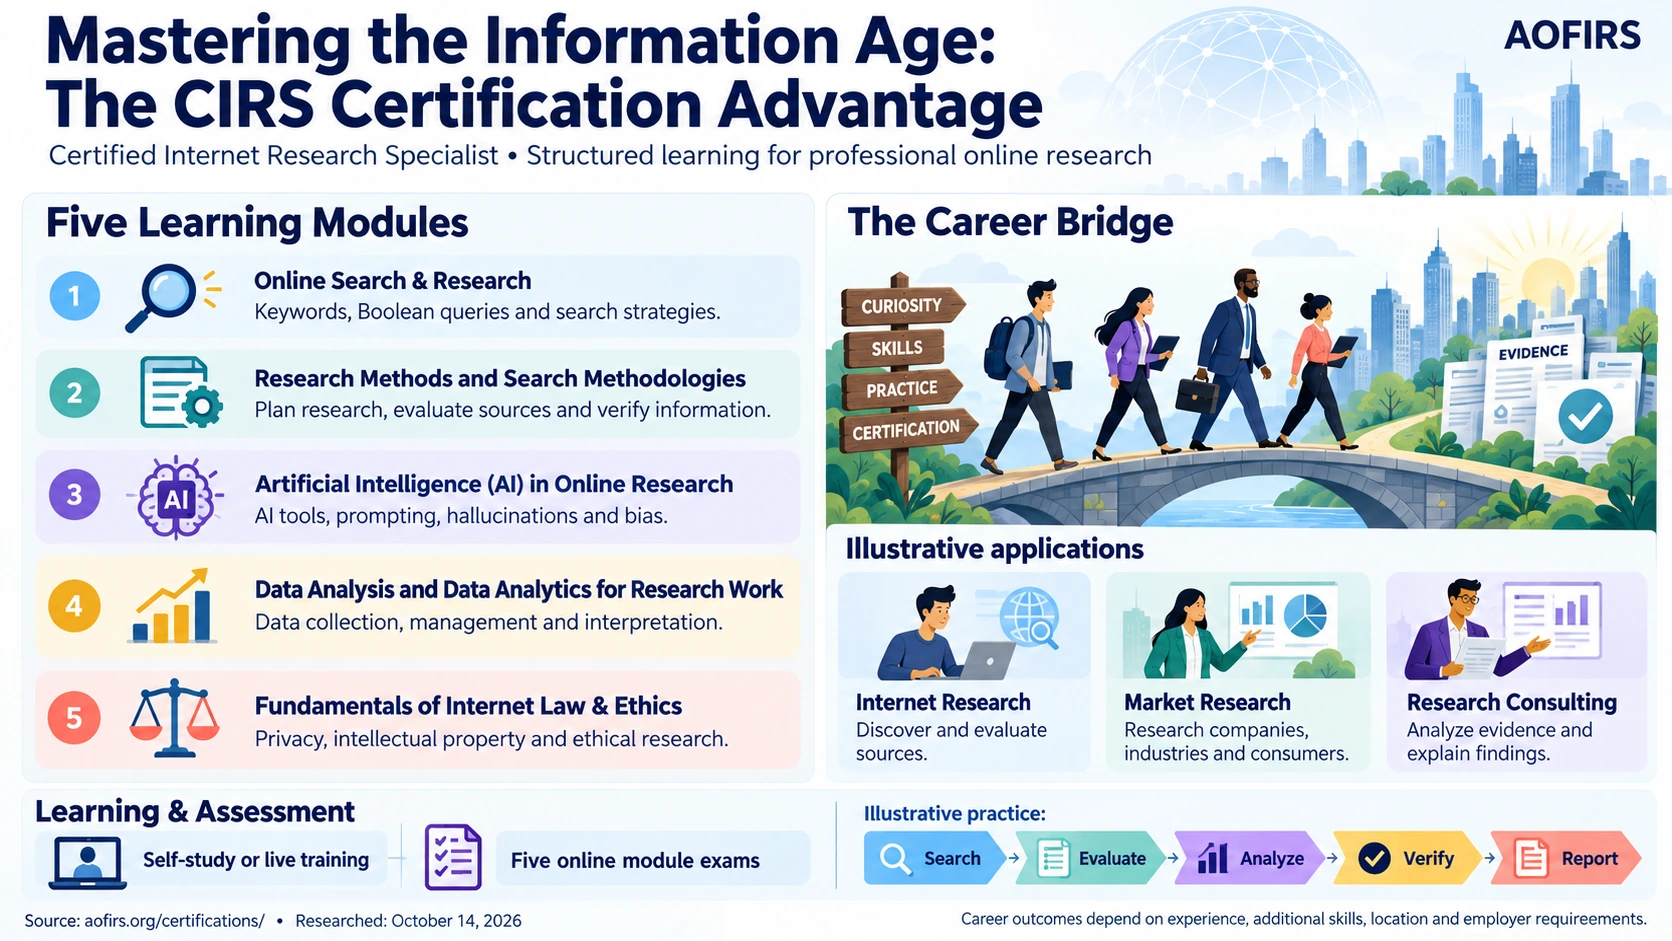
The Certified Internet Research Specialist (CIRS™) program turns these fundamentals into a complete professional methodology: advanced query construction, source verification, deep-web access, and evidence-grade reporting.
Related AOFIRS Resources
- Professional Internet Research: The Mechanics of Search
- Master Google Search: From Keywords to Precision Queries
- Comprehensive Guide to Structured Query Building and Advanced Google Search Operators
- Information Retrieval in the Age of AI
- The Search Architect’s Toolkit
Frequently Asked Questions
What is the difference between crawling and indexing?
Crawling is the act of fetching a page’s content; indexing is the processing and storage of that content in the search engine’s database. A page can be crawled without being indexed — for example, when it carries a noindex directive or is judged duplicate or low-value.
Why does a page I can visit not appear in search results?
Common reasons include robots.txt blocking, noindex meta tags, lack of inbound links, JavaScript-rendered content the crawler cannot execute, or consolidation with a duplicate page. Checking the cache and alternate engines helps isolate the cause.
Do advanced operators work on every search engine?
Core operators such as quotes, minus, site:, and OR are widely supported, but syntax and reliability vary. Google, Bing, and DuckDuckGo each implement field operators differently, so professionals verify operator behavior per engine.
How fresh is a search engine’s index?
It varies by site authority and update frequency. High-authority news sites may be re-crawled within minutes; low-traffic pages can go weeks between crawls. Date-restriction operators and news-specific verticals help target the freshest indexed content.
Can I search content that search engines have not indexed?
Not through the engine’s index — but you can use site-internal search, specialized databases, the deep web, and archival services. A large share of the web’s valuable content lives outside general-purpose indexes.