Search engines do not parse natural language or query syntax identically. While Google relies on an implicit AND, the capitalized OR union operator, and the prepended hyphen (-term) for exclusion, engines like Bing and Yandex enforce fundamentally different syntactic grammars. Bing recognizes explicit & intersection and specialized metadata operators like contains: and ip:, while Yandex enforces sentence-level (&, ~) versus document-level (&&, ~~) Boolean operators, morphological locks (!word, !!word), and document-wide exclusion (---). At the browser layer, user agents like Safari and Firefox do not evaluate search logic; instead, they function as transport routing pipelines, providing direct site bypasses via Safari Quick Website Search and Firefox Smart Keywords. Professional digital investigators and intelligence analysts must navigate this cross-engine matrix to eliminate blind spots and prevent the silent omission of unindexed evidence.

For a quick-glance slide view of retrieval architecture, see the companion slide deck on Engineering the Query: A Cross-System Architecture for Advanced Information Retrieval. For comprehensive technical modules on operator grammar, explore the full research report on Structured Query Building, Keywords, and Advanced Google Search Operators, and test hands-on methodology in The Search Architect’s Toolkit.
The Two Architecture Layers: Browser Layer vs. Search Engine Layer
Every online search request passes through two distinct technological layers before results reach the screen. Failing to understand the boundary between the Browser Layer and the Search Engine Layer creates fundamental misconceptions about how queries execute and why specific operators fail.
Layer 1 Browser Layer (Client / Transport)
The web browser acts strictly as a User Agent (UA). It receives character input, handles character encoding (such as UTF-8 percent-encoding for spaces, slashes, and ampersands), manages DNS lookups, and dispatches HTTP/HTTPS GET requests to external endpoints. Crucially, browsers do not interpret or parse Boolean search logic. A browser treats site:gov "financial fraud" simply as an alphanumeric text string to append to a query parameter string (e.g., ?q=...). However, modern browsers provide internal routing mechanisms—such as Safari Quick Website Search and Firefox Smart Keywords—that bypass general search engines entirely to target specific repository endpoints.
Layer 2 Search Engine Layer (Server / Index Parsing)
The search engine infrastructure receives the raw query string on its ingestion gateways. Lexical parsers tokenize the string into discrete terms, evaluate recognized operators (such as Boolean junctions, filetype specifiers, and domain boundaries), strip ignored noise words, resolve morphological stems, and execute lookups across massive distributed inverted indexes. Because each commercial crawler (Google, Bing, Yandex, DuckDuckGo) operates a proprietary index schema, an operator supported on one engine may be parsed as a literal keyword, discarded as an invalid token, or trigger a complete syntax error on another.
Browser Layer Mechanics: Direct-Site Routing & Smart Shortcuts
Professional researchers avoid routing every inquiry through general commercial search engine homepages. Doing so incurs unnecessary algorithmic filter bubbles, triggers ad tracking, and frequently misses dynamic database entries buried behind web forms. Modern user agents provide powerful client-side routing mechanisms that streamline targeted research.
1. Safari Quick Website Search
Safari includes an intelligent client-side discovery feature known as Quick Website Search. As you browse and search within structured internal websites (such as Wikipedia, GitHub, or specialized government registries), Safari parses the site’s OpenSearch description XML or tracks its internal search form submissions. Once logged, typing the domain name followed by search terms into Safari’s Smart Search Field (omnibar) dispatches the query directly to that website’s internal search engine, bypassing Google or Bing entirely. For example, typing wikipedia forensic accounting in Safari navigates directly to Wikipedia’s internal search results page, eliminating third-party tracking and ad-laden intermediaries.
2. Firefox Smart Keywords & Omnibar Routing
Firefox offers one of the most powerful workflow tools for intelligence analysts: Smart Keywords. By bookmarking any search results page and replacing the query string with %s, researchers can assign single-letter or short mnemonic prefixes in Firefox’s bookmark properties. For example:
sec %s→https://www.sec.gov/edgar/searchedgar/companysearch?companyName=%sgh %s→https://github.com/search?q=%sw %s→https://en.wikipedia.org/w/index.php?search=%s
Furthermore, modern Firefox supports native @ engine routing directly in the address bar (e.g., @google, @bing, @duckduckgo, @wikipedia). This allows researchers to toggle seamlessly between discrete search indices from a single keystroke without loading engine landing pages.
The Search Engine Layer: The Syntax Fragmentation Problem
In the early days of information science, ISO and ANSI standards attempted to unify Boolean information retrieval syntax. However, modern commercial search engines diverged into proprietary implementations optimized for their specific business models, linguistic target markets, and crawl architectures. A syntax string that delivers high-precision intelligence on Google can silently fail or return noisy junk on Bing or Yandex.
Google Engine Semantic Clustering
Google has increasingly shifted toward natural language processing (RankBrain, MUM, Gemini) and semantic clustering. While Google honors core operators like site: and quotes, it frequently applies loose synonyms to unquoted words and ignores Boolean operators unless capitalized. The minus sign (-) must be attached directly to the excluded token without spaces.
Bing Engine Enterprise & Metadata Indexing
Bing retains closer architectural ties to enterprise relational query models. It supports explicit ampersand (&) conjunctions alongside AND, provides powerful metadata operators like contains: (which targets document links rather than body text), and supports network infrastructure queries via ip:.
Yandex Engine Morphological & Sentence Logic
Yandex is engineered for Slavic and complex synthetic languages where words inflect through dozens of grammatical cases. Consequently, Yandex provides the world’s most sophisticated public morphological and document-distance operators, distinguishing between sentence-level and document-wide Boolean logic.
The Cross-Engine Boolean Triad: Google vs. Bing vs. Yandex
Understanding how the three fundamental Boolean relationships—Intersection (AND), Union (OR), and Exclusion (NOT)—are expressed across primary crawlers is the foundation of precision query engineering.
1. Intersection (AND Logic)
Intersection mandates that all specified concepts must be present in retrieved results:
- Google: Evaluates spaces between terms as an implicit
AND. Explicit capitalizedANDis also supported (e.g.,"offshore entity" AND "Panama"). Lowercaseandis treated as a regular stopword. - Bing: Supports space as implicit
AND, capitalizedAND, and the literal ampersand symbol (&). - Yandex: Enforces a critical structural distinction: a single ampersand (
&) mandates sentence-level co-occurrence (both terms must appear within the exact same grammatical sentence), whereas a double ampersand (&&) mandates document-level co-occurrence (terms can appear anywhere within the document). This distinction prevents false-positive associations across multi-page articles.
2. Union (OR Logic)
Union expands recall by allowing any of the specified terms or phrases to satisfy the retrieval condition:
- Google: Requires capitalized
ORor the pipe symbol (|). Lowercaseoris treated as an unindexed noise word. Parentheses must be used to group union clauses (e.g.,"money laundering" (shell OR conduit OR nominee)). - Bing: Honors capitalized
ORand the pipe symbol (|), allowing identical parenthetical grouping. - Yandex: Uses the pipe symbol (
|) for union. Multiple synonymous terms are grouped in standard parentheses:(fraud | embezzlement | bribery).
3. Exclusion (NOT Logic)
Exclusion prunes irrelevant noise, commercial aggregators, and false-positive homonyms from results:
- Google: Enforces the hyphen/minus operator attached directly to the excluded keyword (e.g.,
-wikipedia -"press release"). Crucially, there must be a preceding space before the hyphen and no space between the hyphen and the word. Google does not recognizeNOTas a functional operator. - Bing: Recognizes both the prepended hyphen (
-keyword) and the explicit capitalized operatorNOT(e.g.,cybercrime NOT crypto). - Yandex: Uses the tilde (
~) for sentence-level exclusion (the excluded word must not appear in the same sentence as the matched word) and double tilde (~~) for document-wide exclusion. Yandex also supports---for broad negative filtering.
Masterclass: Advanced Query Construction & Search Precision
In this instructional masterclass from the AOFIRS Video Library, professional researchers break down the mechanics of moving beyond basic keyword queries. The presentation examines how search engines parse complex strings, how to construct disciplined Boolean filters, and how to eliminate algorithmic distortion during open-source investigations.
The Cross-Engine Syntax Comparison Matrix
The following technical reference matrix provides side-by-side operator specifications across Google, Bing, and Yandex, complete with practical analyst guidance for investigative deployment:
| Retrieval Function | Google Syntax | Bing Syntax | Yandex Syntax | Investigative Application & Notes |
|---|---|---|---|---|
| Implicit AND | term1 term2 |
term1 term2 |
term1 term2 |
Standard default across all engines. Evaluates basic term co-occurrence. |
| Explicit AND | term1 AND term2 |
term1 AND term2term1 & term2 |
term1 && term2 (doc)term1 & term2 (sentence) |
Use Yandex single & to ensure target entities appear in the exact same sentence. |
| Union (OR) | term1 OR term2term1 | term2 |
term1 OR term2term1 | term2 |
term1 | term2 |
Must capitalize OR in Google/Bing. Pipe symbol | works universally. |
| Exclusion (NOT) | -keyword |
NOT keyword-keyword |
~~keyword (doc)~keyword (sentence)--- |
Google requires no space after minus: -spam. Yandex ~ removes false associations without killing document. |
| Exact Phrase | "exact phrase" |
"exact phrase" |
"exact phrase" |
Disables engine synonym expansion and enforces rigid token sequencing. |
| Morphology Lock | "word" (approx) |
"word" (approx) |
!word (exact case)!!word (base lemma) |
Google/Bing still stem quoted words in certain cases. Yandex ! forces exact grammatical inflection. |
| Domain Filter | site:domain.com |
site:domain.com |
site:domain.comurl:"domain/*" |
Restricts index retrieval to specified TLD or hostname. Do not include http://. |
| File Type | filetype:pdfext:pdf |
filetype:pdf |
mime:pdf |
Google/Bing accept filetype:. Yandex requires mime: for true MIME-type header filtering. |
| Link Containment | Deprecated | contains:pdf |
Not supported | Bing contains: locates pages linking to a specific file extension, ideal for finding download hubs. |
| Host / Server IP | Not supported | ip:192.0.2.1 |
Not supported | Bing unique operator: discovers all co-hosted virtual domains sharing a single server IP address. |
| In Title | intitle:termallintitle:a b |
intitle:term |
title:term |
Targets HTML <title> tags. Essential for isolating executive resumes and formal reports. |
| In URL Path | inurl:termallinurl:a b |
inurl:term |
inurl:term |
Filters URL directory paths (e.g., inurl:wp-content/uploads or inurl:staff-directory). |
| Word Distance | AROUND(n) |
near:n (legacy) |
/n (sentence)//n (adjacent)&&/n (document) |
Google AROUND(5) forces proximity within 5 words. Yandex provides granular sentence and document distance controls. |
Advanced Metadata Filtering & Engine-Specific Nuances
Beyond basic Boolean combinations, mastering precision retrieval requires deploying engine-specific operators tailored to distinct analytical objectives:
1. Bing’s Specialized Infrastructure Operators
While Google commands dominant consumer market share, Bing provides unique infrastructure intelligence capabilities invaluable to OSINT investigators:
- The
ip:Operator: Enteringip:198.51.100.24lists all domains and subdomains indexed by Bing on that specific server. This enables reverse IP lookup without relying on commercial subscription databases, uncovering hidden sister sites and affiliate fraud networks. - The
contains:Operator: Unlikefiletype:pdf, which finds standalone PDF documents,contains:pdflocates web pages that contain active hyperlinks to PDF files. This is ideal for finding password-protected resource centers, download portals, and unlinked document repositories. - The
feed:andprefer:Operators:feed:osintidentifies active RSS and Atom feeds for intelligence monitoring.prefer:termallows researchers to add positive weighting to specific terminology without rigidly excluding documents that lack the word.
2. Yandex’s Morphological & Proximity Precision
Yandex provides an unrivaled suite of operators designed to eliminate the ambiguity of natural language stemming:
- Morphology Locks (
!and!!): Modern search engines automatically stem search terms (e.g., searching for “investigate” returns “investigating,” “investigation,” and “investigators”). In complex legal or corporate inquiries, this causes extreme dilution. In Yandex, placing an exclamation mark before a word (e.g.,!Director) disables grammatical stemming and matches that exact morphological form. A double exclamation mark (!!word) restricts matching to the base dictionary lemma. - Granular Proximity Operators: While Google offers only
AROUND(n), Yandex supports directional and structural distance filters:term1 /+n term2(term1 precedes term2 by n words),term1 /-n term2(term1 follows term2 by n words),term1 //n term2(terms within n words across sentence breaks), andterm1 &&/n term2(terms within n sentences across the entire document).
Practical Query Engineering Protocols for Investigators
To conduct rigorous, defensible digital investigations, researchers should follow a structured four-stage query engineering protocol:
Stage 1 Conceptual Decomposition
Break the investigative hypothesis into core conceptual vectors: Target Entity, Operational Context, Geographic Boundary, and Document Typology. Identify mandatory root terms, exact acronyms, and statutory synonyms before typing a single character into an engine.
Stage 2 Cross-Engine Syntax Adaptation
Translate the conceptual query into engine-specific syntax strings. Do not copy-paste a Google query into Bing or Yandex. Adjust operator capitalization, convert filetype: to mime: for Yandex, and utilize contains: or ip: when operating in Bing.
Stage 3 Iterative Negative Pruning
Audit the initial result set for repetitive commercial spam, job aggregator boards, and SEO scraper farms. Append disciplined negative filters (e.g., -careers -glassdoor -indeed -"press release") to strip irrelevant noise without clipping investigative leads.
Stage 4 Multi-Engine Triangulation
Execute parallel queries across Google, Bing, Yandex, and specialized academic/legal repositories. Compare corpus overlap. In open-source investigations, an entity with zero indexed records on Google may have extensive footprints cataloged in Yandex or Bing indexes.
Advance Your Digital Research Skills: The CIRS™ Credential
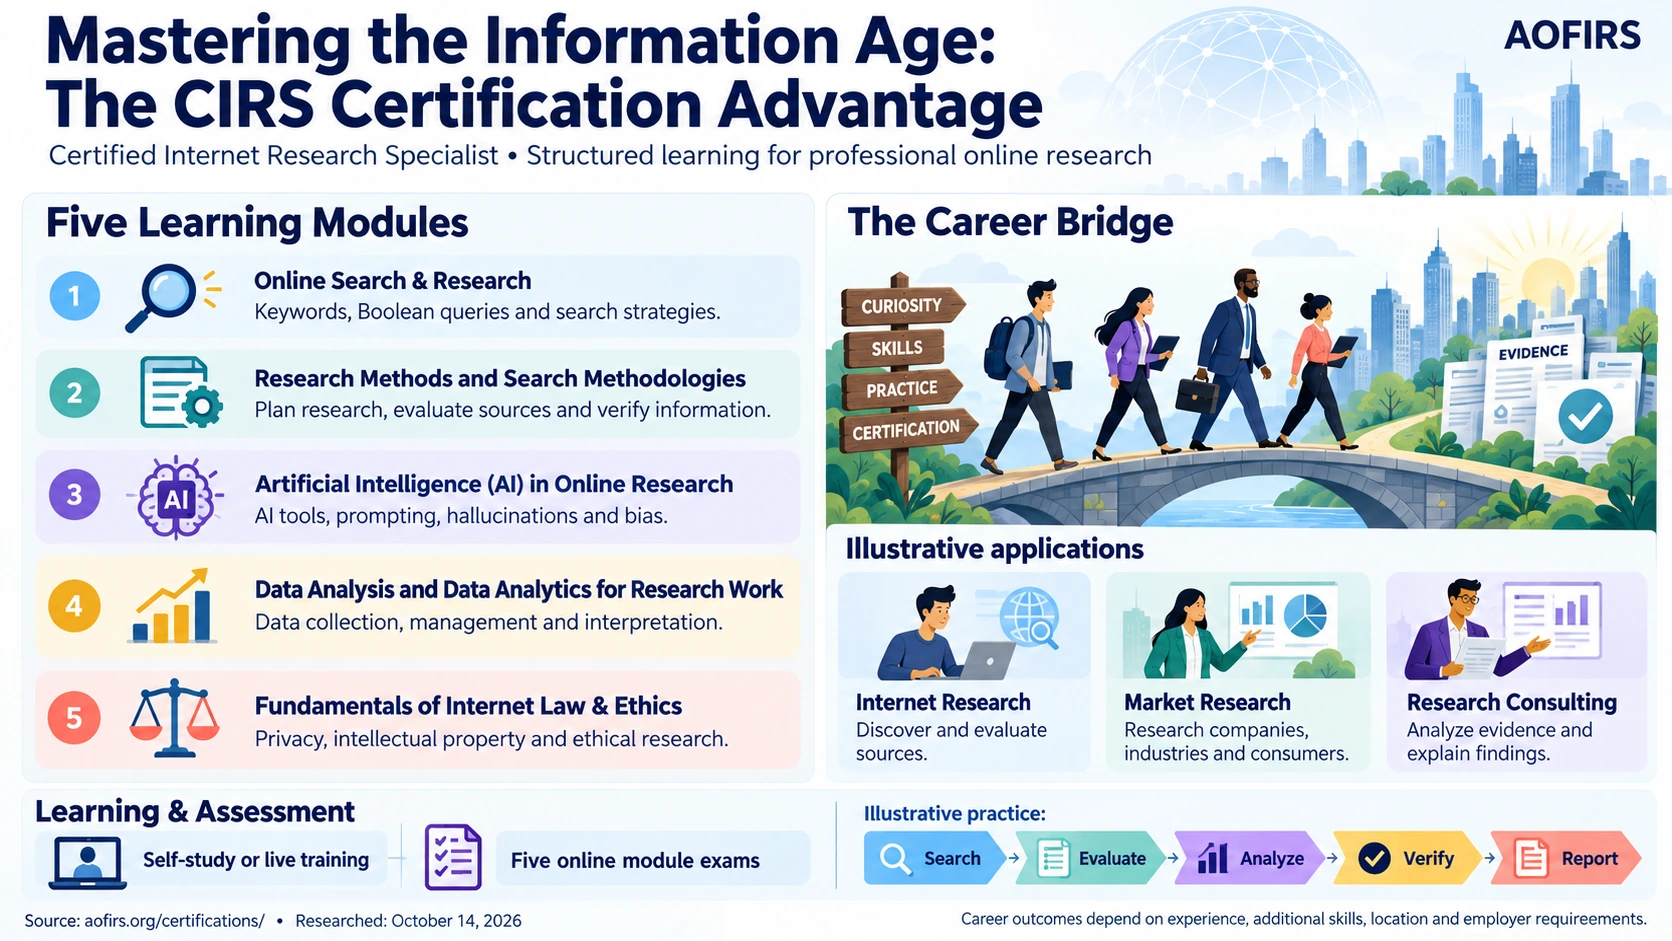
Structured query engineering, advanced Boolean logic, metadata filtering, and cross-engine verification form the core foundation of Module 1 in the Certified Internet Research Specialist (CIRS™) curriculum. Designed for intelligence analysts, investigative journalists, compliance officers, and researchers worldwide, the CIRS certification provides verified competence in defensible information retrieval.
Essential Research Resources
- Engineering the Query: A Cross-System Architecture for Advanced Information Retrieval — Companion slide deck exploring cross-system information retrieval architectures.
- Structured Query Building, Keywords, and Advanced Google Search Operators — In-depth AOFIRS research report on advanced search operator syntax.
- The Search Architect’s Toolkit — Advanced search methodology, precision query engineering, and investigator workflows.
- The Modern Investigator’s Map: Navigating Public & Private Data — Navigating permissible purpose, statutory protections, and record access tiers.
- AOFIRS CIRS Certification Program — Professional certification framework for internet research specialists.
Frequently Asked Questions
Why does a query that works perfectly on Google return zero results on Yandex or Bing?
Search engines utilize proprietary query parsers, distinct indexing algorithms, and divergent operator grammars. For instance, Google recognizes lowercase space as an implicit AND and allows the hyphen -word for exclusion. Yandex distinguishes between sentence-level (&) and document-level (&&) operators, requires mime: rather than filetype:, and utilizes tildes (~) for exclusion. Furthermore, each engine maintains a completely distinct index of the web; regional crawlers like Yandex index Eastern European and non-Latin domains far more aggressively than Google, while Bing indexes different enterprise and network assets.
How does Yandex’s exclamation mark operator differ from standard quotation marks?
Quotation marks ("phrase") enforce exact word order and token adjacency across all major engines, but Google and Bing may still apply light grammatical stemming to individual words inside quotes in certain contexts. Yandex’s exclamation mark operator (!word) specifically disables morphological analysis and stemming, forcing the search engine to match only the exact grammatical case, number, tense, and gender of the word entered. A double exclamation mark (!!word) matches all forms derived from that exact dictionary lemma.
Can a web browser process Boolean search operators before sending a query?
No. Web browsers function strictly as User Agents at the transport layer. They handle text entry, character encoding, and HTTP/HTTPS protocol handshakes, transmitting your raw text string to the destination server query parameter. The browser does not evaluate AND, OR, or NOT logic. However, modern browsers provide client-side shortcut routing (such as Safari Quick Website Search and Firefox Smart Keywords) that allows researchers to bypass search engines entirely and dispatch queries directly to site-specific search interfaces.
What is the difference between Bing’s filetype: and contains: operators?
The filetype:pdf operator searches for documents that are themselves formatted as PDF files and indexed by the crawler. In contrast, Bing’s unique contains:pdf operator searches for standard web pages (HTML) that contain active outbound hyperlinks pointing to PDF files. This is an invaluable OSINT technique for uncovering document repositories, financial audit archive portals, and download centers that might otherwise remain unindexed.
Why is relying solely on Google dangerous for professional OSINT and legal research?
Relying on a single search engine creates severe analytical blind spots. Google’s algorithmic results are heavily influenced by geographic localization, historical personalization, aggressive commercial clustering, and algorithmic “helpfulness” filters that suppress raw technical documents. Furthermore, copyright de-indexing (DMCA), right-to-be-forgotten requests, and commercial ad models mean Google omits significant portions of the visible web. Cross-engine validation across Bing, Yandex, and specialized vertical databases is required to establish defensible, comprehensive research findings.
Published by the Association of Internet Research Specialists (AOFIRS) • Research & Educational Publications • Updated October 2026