Advanced query engineering is the discipline of structuring information retrieval requests to match the underlying database schemas, tokenization pipelines, and Boolean logic of specific search systems—separating client-side browser routing from database parsing engines across Google, Bing, and Yandex.
1. The Core Architectural Axiom: Browsers Route, Engines Parse
A frequent error among digital investigators is treating the web browser address bar (Omnibox) as a search engine. In modern network architecture, the User Agent (the browser) and the Information Retrieval System (the search database) operate across a fundamental translation gap. Browsers do not evaluate Boolean operators, execute proximity math, or parse metadata boundaries. Instead, the browser functions as a lexical interceptor that routes raw Unicode strings into encoded HTTP GET request parameters.
When an investigator types a query such as how to build complex queries inurl:admin into Safari or Firefox, the browser captures the entire string, converts spaces into delimiters, and delivers an encoded payload across the network. Only when it reaches the provider’s ingestion clusters (Google, Bing, or Yandex) does the information retrieval system’s tokenizer disassemble the string into literal terms, logical directives, and metadata filters. Mastering advanced research requires structuring inputs precisely for the target engine’s parser rather than relying on browser heuristics.
2. Intercepting at the Omnibox: Firefox Smart Keywords & Safari Privacy Shield
Professional query engineering begins at the client level before any network packet leaves the local workstation. By establishing custom browser routing configurations, analysts bypass commercial search telemetry, avoid algorithmic query rewriting, and transmit commands directly into target databases.
Firefox Smart Keywords & Direct Routing
Firefox allows investigators to assign custom search tags and prefix characters (such as @y for Yandex, @b for Bing, or @w for Wikipedia). When invoked in the Omnibox, Firefox isolates the subsequent query tokens, bypasses the browser’s default regional search engine, and executes a direct HTTP parameter injection to the specified engine’s endpoint without query scrubbing.
Safari Quick Website Search & Privacy Shield
Safari indexes the structure of internal website search inputs during browsing sessions. Typing an internal site name followed by a query triggers a direct database query. Crucially, Safari’s Privacy Shield strips third-party tracking parameters and tracking telemetry from the payload before it leaves the browser workstation.
3. Cross-Engine Boolean Parsing Standards
While the mathematical foundation of Boolean logic (George Boole, 1854) is universal, its practical implementation varies drastically across proprietary search engine indexers. Understanding how Google, Bing, and Yandex handle logical operators prevents false exclusions and missed intelligence.
Exact Phrase Match ("keyword phrase")
Universally supported across Google, Bing, and Yandex. Enforces exact lexical order, token proximity, and prevents algorithmic synonym substitution or semantic fuzzy expansion.
Logical Union (OR or |)
Google and Bing require capitalized OR or the vertical bar pipe |. Yandex supports | for sentence union and double pipe || for document-level logical union.
Mandatory Token Enforcement (+)
In Google, the historical + operator has been deprecated in favor of double quotes. In Yandex, however, +keyword serves a crucial grammatical function: it disables Russian and Slavic morphological stemming, forcing the engine to match the exact grammatical inflection and case.
Logical Exclusion (-, NOT, ~)
Google strictly requires a hyphen immediately preceding the excluded token without spaces (-keyword). Bing accepts both -keyword and capitalized NOT keyword. Yandex utilizes the tilde (~) for sentence-level exclusion and double tilde (~~) for document-wide negation.
4. Yandex’s Architectural Divergence: Sentence Scope vs. Document Scope
The most profound divergence in global search engine design occurs between Western indexers (Google, Bing) and Yandex. Western engines apply Boolean operators universally across the entire indexed text of a webpage. A page containing Term A in the header and Term B in the footer 3,000 words later will satisfy a standard AND query in Google, generating severe false positives.
Yandex solves this architectural limitation by distinguishing between Sentence-Level Scope and Document-Level Scope through specialized syntactic operators:
Sentence Scope Operators (& and ~)
A single ampersand (&) restricts the logical intersection strictly to the grammatical boundaries of a single sentence. Similarly, a single tilde (~) excludes a term only if it appears within the exact sentence containing the primary keyword, preserving the document if the excluded term appears elsewhere.
Document Scope Operators (&& and ~~)
Double ampersands (&&) expand the logical intersection across the entirety of the indexed document, mirroring standard Western Boolean behavior. Double tildes (~~) enforce document-wide negative exclusion, purging the entire URL if the prohibited term appears anywhere on the page.
5. Vector Targeting: Metadata & Index Boundary Operators
In addition to raw body text, search engines index metadata vectors including URLs, document headers, file MIME types, and host domains. Precision researchers leverage metadata operators to target specific document architectures directly:
| Target Vector | Google / Bing Standard | Yandex Proprietary | Investigative Utility |
|---|---|---|---|
| File Type / MIME | filetype:pdf or ext:pdf |
mime:pdf |
Isolates authoritative research papers, white papers, financial statements, and technical slide decks. |
| Host / Domain | site:gov or site:example.com |
site:gov or domain:gov |
Restricts query execution to verified top-level domains, government repositories, or corporate portals. |
| Page Title | intitle:"confidential" / allintitle: |
title:"confidential" |
Retrieves documents where core investigative keywords appear in the HTML <title> header element. |
| URL Path & Slug | inurl:"wp-content" / allinurl: |
inurl:"admin" / rhost: |
Targets directory structures, specific API endpoints, media repositories, and administrative paths. |
| Body Text Only | intext:"sanctions list" |
intext:"sanctions" |
Forces matching within document copy while disregarding terms appearing solely in navigation menus or sidebars. |
| Anchor Text | inanchor:"download report" |
Indexed via Link Graph | Discovers resources based on how external webmasters hyperlink to the target file. |
6. Distance & Proximity Mechanics: Mathematical Word Windows
When searching unstructured text repositories, Boolean intersection (AND) often fails because keywords appear too far apart to be contextually related. Proximity operators constrain the maximum allowable distance between search tokens, drastically elevating precision.
| Engine | Proximity Operator | Execution Syntax | Functional Mechanics |
|---|---|---|---|
AROUND(n) |
"subpoena" AROUND(5) "offshore" |
Matches both tokens within a window of n words in any order. The operator name must be uppercase. | |
| Bing | NEAR:n |
"board meeting" NEAR:3 "resignation" |
Enforces a maximum distance of n words between the specified terms, prioritizing closer occurrences. |
| Yandex | /n, /+n, /-n |
"fraud" /3 "investigation" |
/n specifies distance in words. /+n enforces strict forward order, while /-n enforces backward order. |
| Yandex Sentence | && /(-n +m) |
"director" && /(-2 +4) "bank" |
Constructs asymmetrical word distance windows relative to the anchor keyword position. |
Masterclass Video: Advanced Query Construction & Retrieval Precision
Watch the AOFIRS masterclass on structuring complex queries, leveraging cross-engine operators, and bypassing algorithmic search noise.
7. Structured Query Formulation Protocol: The 4-Stage Lifecycle
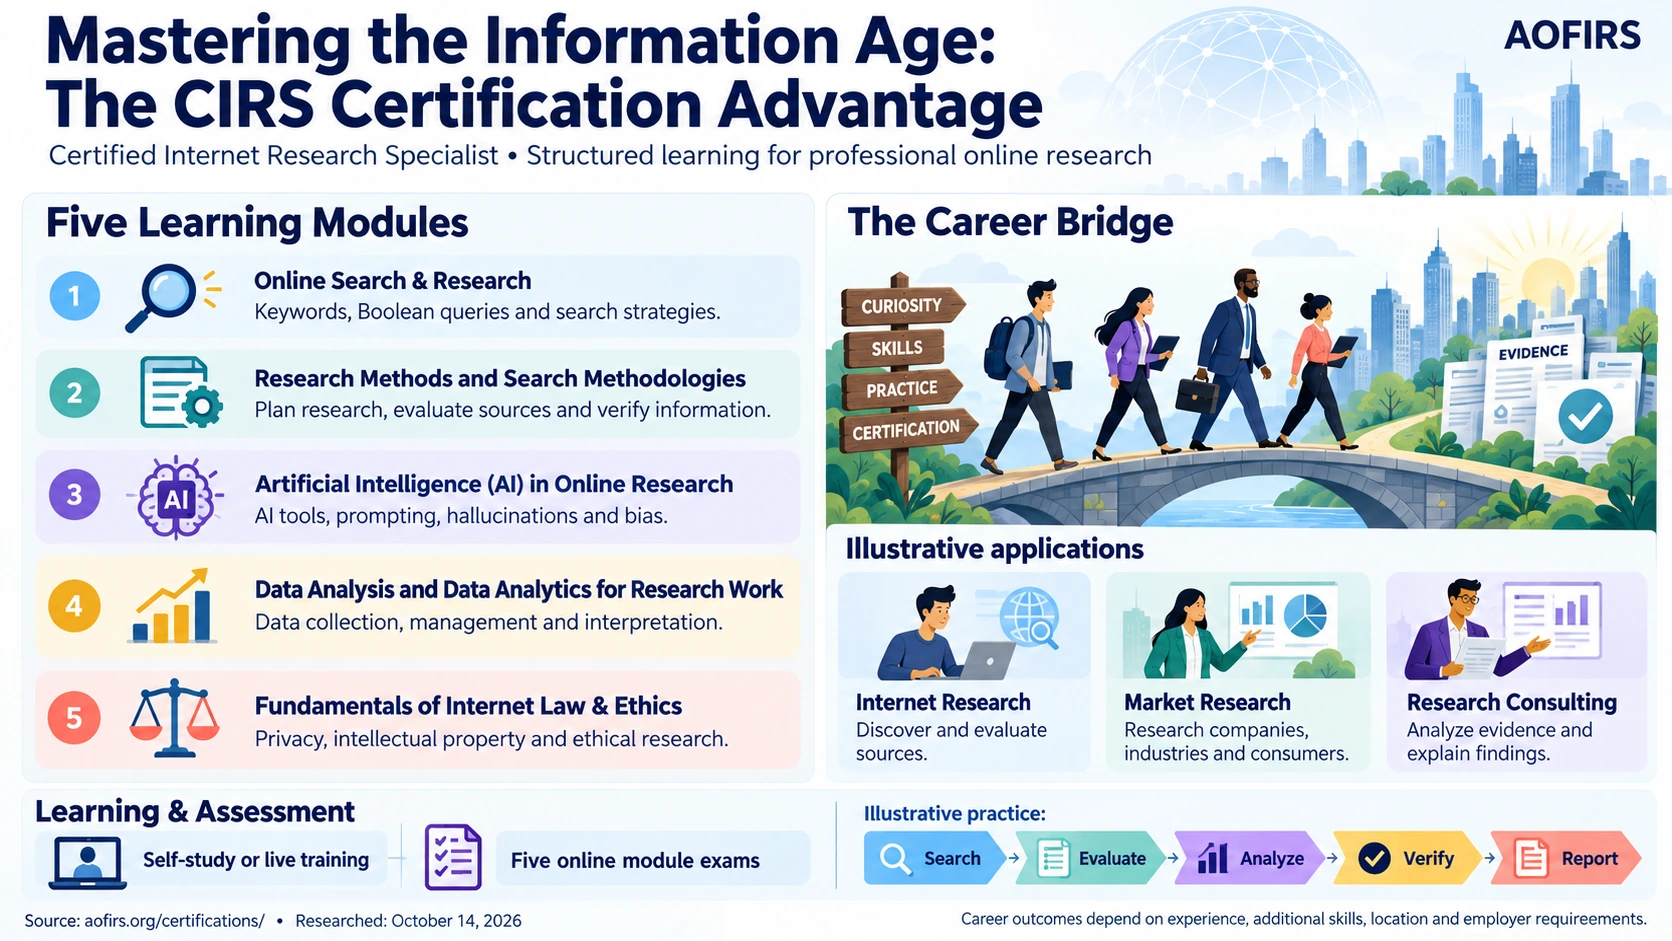
Professional information retrieval requires moving away from ad-hoc keyword entry toward structured query engineering. The CIRS™ methodology establishes a 4-stage operational lifecycle for complex investigations:
Stage 1: Question Decomposition
Break the research objective into core thematic entities, distinguishing required actors, actions, locations, and timeframes. Identify high-value discriminating identifiers (e.g., registration numbers, technical codes).
Stage 2: Morphological Expansion
Generate synonyms, acronyms, regional spelling variations, and language inflections. In multilingual research (such as Cyrillic indexing on Yandex), determine whether morphological stemming should be permitted or pinned with +.
Stage 3: Operator Parameterization
Select target repositories and translate Boolean logic into engine-native syntax. Apply index boundaries (site:, filetype:, mime:) and proximity constraints (AROUND(n), /n) to exclude non-relevant domains.
Stage 4: Triangulation & Verification
Execute parallel queries across competing engines to compensate for index blind spots. Verify returned sources against primary registry filings, original PDF headers, and cryptographic timestamps.
Advance Your Research Craft: The CIRS™ Credential
Develop structured query formulation, multi-engine retrieval protocols, and evidentiary verification methodologies through the Certified Internet Research Specialist (CIRS™) certification program.
Frequently Asked Questions
Why does the web browser address bar (Omnibox) behave differently than a direct search engine query?
The web browser (User Agent) operates as a client-side routing application, not an information retrieval engine. The Omnibox encodes text into standard HTTP GET URI parameters according to RFC 3986. It does not parse Boolean logic, proximity operators, or metadata boundaries. If an Omnibox has built-in auto-correct or search suggestions enabled, it may alter or strip unrecognized punctuation before transmitting the query to the remote search provider.
How does Yandex’s sentence-level operator (&) prevent false positives compared to Google’s AND?
Google’s default Boolean logic operates across the entire document: if Term A appears in the first paragraph and Term B appears 4,000 words later in the footer comments, Google treats the document as an intersection match. Yandex’s single ampersand (&) enforces sentence-level scope, requiring both tokens to appear within the exact grammatical sentence. This eliminates thousands of irrelevant results when researching named entities in extensive multi-topic documents.
What is the operational difference between Google’s AROUND(n) and Yandex’s /n operator?
Google’s AROUND(n) establishes an un-ordered distance window between two tokens, meaning Term A can appear up to n words before or after Term B. Yandex’s proximity syntax provides greater directional precision: /n matches terms within n words in any order, /+n requires the second term to follow the first within n words, and /-n requires the second term to precede the first. This is invaluable when searching for specific titles, legal clauses, or financial agreements.
Why is the plus (+) operator still functional in Yandex when Google deprecated it?
Google historically used + to enforce exact keyword inclusion, but deprecated it in 2011 in favor of quotation marks ("term"). In Yandex, the plus prefix (+keyword) is fundamentally different: because Russian is a highly inflected synthetic language where word endings change based on six grammatical cases, Yandex by default searches all morphological variants. The + symbol explicitly locks the term to its exact grammatical form, disabling automatic stemming.
What is the recommended multi-engine query protocol for open-source investigators?
A rigorous query protocol requires multi-engine triangulation. Analysts should begin with broad structural operators in Google to map the public surface area, transition to Bing to exploit distinct indexation schedules and corporate infrastructure, and deploy Yandex for strict sentence-level proximity and international domain access. Queries should never be copy-pasted across engines without translating operator syntax to the specific engine’s parser rules.