Raw data without methodological structure is noise. In professional research, business intelligence, and investigative inquiry, the ability to collect information is meaningless without the analytical rigor required to validate, synthesize, and interpret it. Data analysis is the disciplined process of inspecting, cleansing, transforming, and modeling raw observations into structured evidence that reveals underlying truths, disproves false assumptions, and drives defensible, strategic decisions.
The Four Pillars of Data Analytics
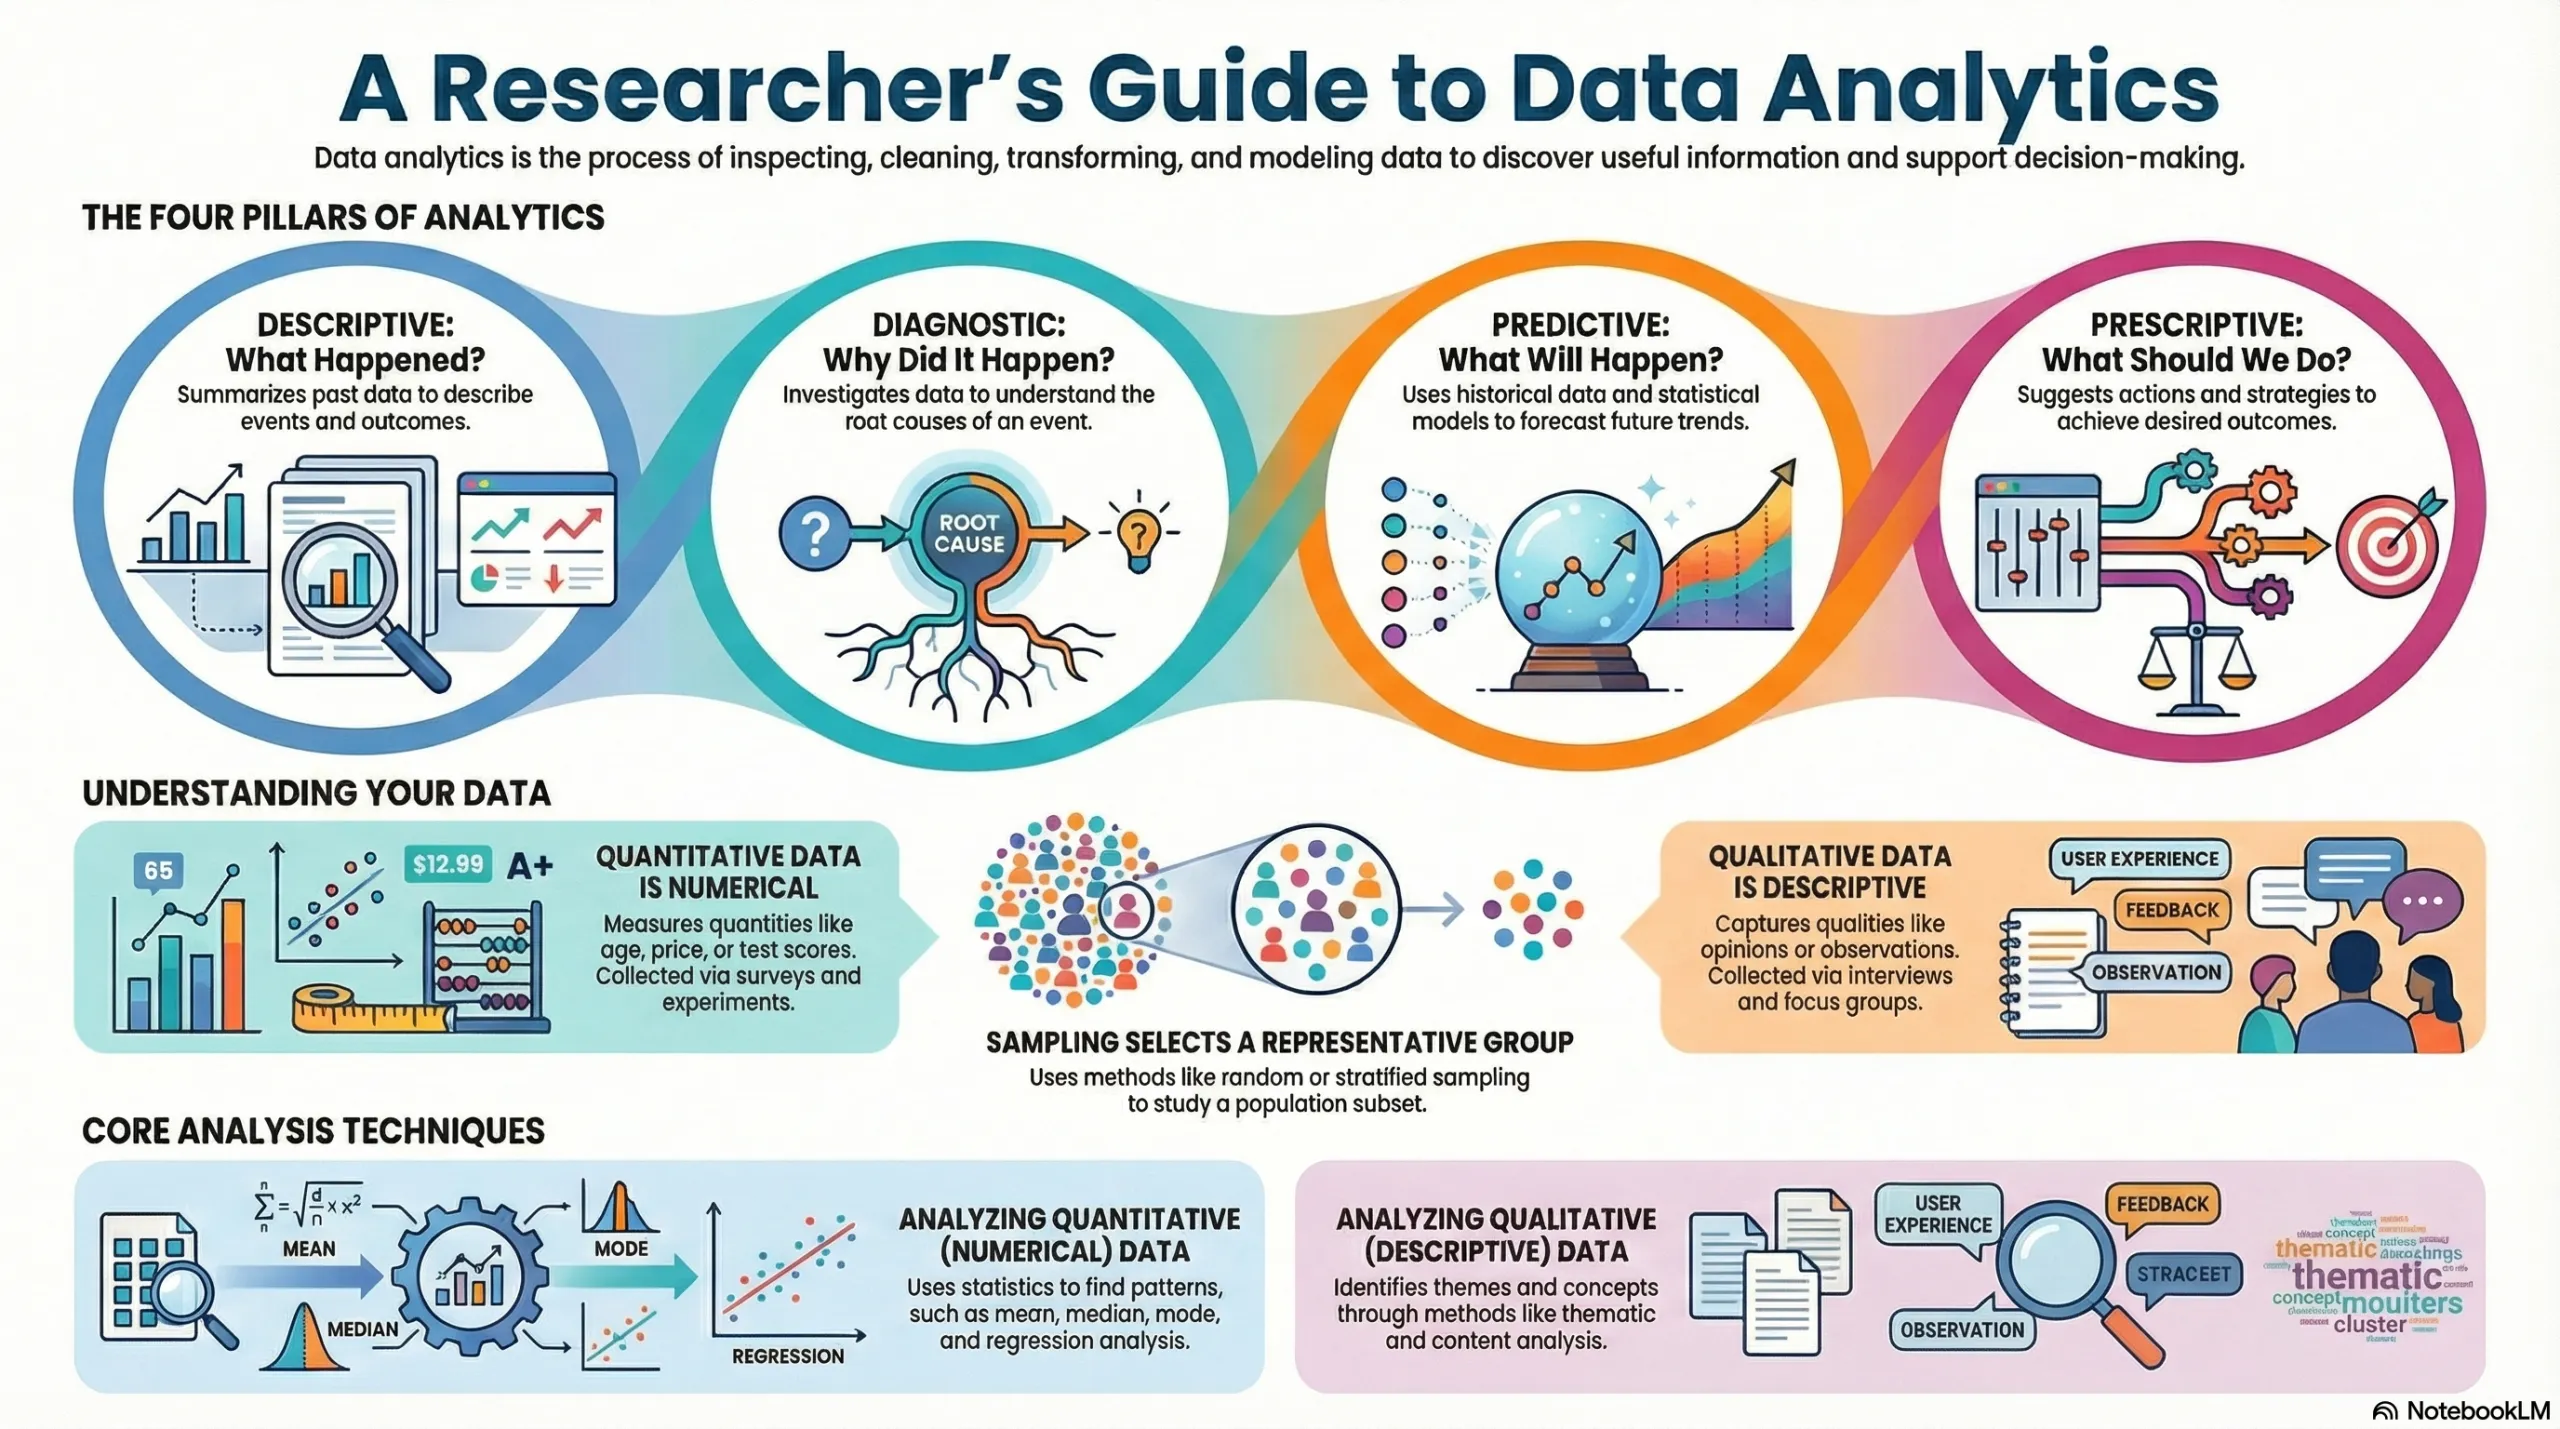
Modern analytical workflows are categorized into four distinct levels of analytical sophistication, each answering a progressively complex operational question:
Aggregates historical data points, calculates summary metrics (mean, median, standard deviation), and visualizes distribution patterns. It establishes baseline reality and historical trajectory across research cohorts.
Drills down into anomalies, isolates confounding variables, and identifies causal relationships or systemic correlations. It uncovers root causes beneath observed metric shifts.
Applies regression models, machine learning algorithms, and historical trend trajectories to forecast plausible future outcomes and assess probabilistic risks.
Utilizes optimization algorithms, simulation modeling, and decision-tree logic to prescribe actionable interventions designed to capitalize on predicted opportunities or mitigate vulnerabilities.
Quantitative vs. Qualitative Data: Bridging the Epistemic Divide
Rigorous research rarely relies on a single data typology. The most defensible findings emerge from triangulating quantitative metrics with qualitative contextual depth:
| Analytical Dimension | Quantitative Analysis | Qualitative Analysis |
|---|---|---|
| Nature of Observations | Numerical values, continuous measurements, discrete frequency counts, and standardized interval metrics. | Textual narratives, observational field notes, interview transcripts, visual artifacts, and contextual nuance. |
| Core Questions Answered | “How many?”, “How much?”, “How frequently?”, and “What is the statistical significance?” | “Why?”, “How?”, “What underlying meanings or cultural mechanisms drove this behavior?” |
| Methodological Approaches | Hypothesis testing, ANOVA, multivariate regression, factor analysis, and Bayesian probability distributions. | Thematic coding, grounded theory, discourse analysis, content analysis, and ethnographic immersion. |
| Inherent Strengths | High generalizability, reproducibility, objective comparability, and mathematical precision across large samples. | Rich contextual depth, exposure of subtle behavioral nuances, and discovery of unexpected exploratory hypotheses. |
| Primary Vulnerabilities | Oversimplification of complex human motives; blindness to unmeasured confounders; vulnerability to sampling bias. | Subjective researcher bias; lack of statistical generalizability; intensive resource requirements for coding and validation. |
The End-to-End Research Data Pipeline
Transforming disorganized inputs into boardroom-grade intelligence follows a continuous five-stage engineering pipeline:
- Data Ingestion & Acquisition: Gathering structured database records, semi-structured API responses, web-scraped corpora, or observational field surveys while documenting exact provenance and collection timestamps.
- Sanitization & Cleansing: Identifying missing entries, resolving conflicting schema headers, deduplicating records, normalizing date formats, and filtering statistical outliers that distort baseline indicators.
- Exploratory Data Analysis (EDA): Plotting histograms, correlation heatmaps, and scatter distributions to identify structural clusters, skewness, and multi-collinearity before formal hypothesis testing.
- Statistical Synthesis & Modeling: Applying rigorous inferential tests or qualitative thematic frameworks to evaluate primary research questions and assess confidence intervals.
- Defensible Reporting & Visualization: Translating raw analytical outputs into intuitive charts, executive matrices, and transparent methodology disclosures that stand up to peer and regulatory scrutiny.
Video Masterclass: A Guide to Data Analysis
Watch this comprehensive video guide from the AOFIRS Research Analytics Series explaining how analysts structure raw datasets, eliminate bias, and extract reliable insights from complex information environments.
Accelerate Your Analytical Career with CIRS™
The Certified Internet Research Specialist (CIRS™) credential validates your expertise in investigative methodology, open-source intelligence, structured data analysis, and decision-grade reporting.
Related Learning Publications & Research Reports
- The Researcher’s Journey: From Raw Data to Actionable Insight — A visual slide presentation mapping the four analytical maturity tiers.
- Strategic Plan for Data Analysis and Management — Comprehensive governance framework for institutional research repositories.
- The Search Architect’s Toolkit — Advanced retrieval syntax for extracting datasets from the deep web.
- Optimizing the Modern Research Workflow — Integrating quantitative search with AI-powered qualitative synthesis.
- Social Media as an Informative Source — Methodologies for harvesting and evaluating unstructured digital sentiment.
Frequently Asked Questions
What is the difference between raw data, information, and actionable insight?
Raw data consists of unorganized, discrete facts, numbers, or symbols lacking contextual framing. Information emerges when raw data is cleaned, structured, and organized to answer “who, what, when, and where.” Actionable insight represents synthesized knowledge that explains “why” patterns exist and defines specific strategic interventions.
When should a researcher choose qualitative analysis over quantitative methods?
Qualitative analysis is indispensable during early exploratory phases when the underlying variables are unknown, or when investigating intricate human motivations, organizational culture, regulatory interpretations, or ethical concerns that cannot be reduced to numerical metrics without losing critical context.
What is Exploratory Data Analysis (EDA) and why is it mandatory?
Exploratory Data Analysis is the practice of visually and statistically examining data before applying formal models. It reveals data entry errors, identifies skewed distributions, isolates extreme outliers, and confirms whether dataset properties satisfy the assumptions of planned statistical algorithms.
How can analysts prevent confirmation bias in qualitative data interpretation?
Mitigating confirmation bias requires structured coding protocols, blind independent inter-coder agreement testing, deliberate search for disconfirming evidence, and documenting negative cases where the prevailing hypothesis failed to explain observations.
Is the high-resolution Data Analysis infographic free to download?
Yes. The full 2560 × 1429 pixel infographic can be viewed above and downloaded free in high-resolution PNG format for training, academic research, and reference use.