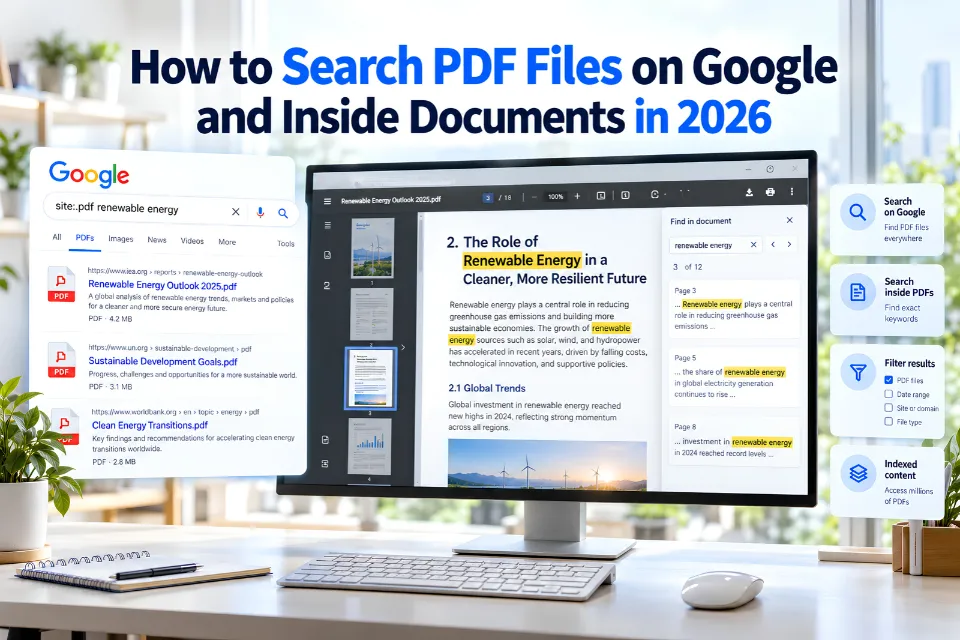
To find PDFs on Google, add filetype:pdf to your topic, such as climate change report filetype:pdf. To search an open PDF, use Find: Ctrl+F on Windows or Command+F on Mac. If the file is an image-only scan, OCR may be needed to create searchable text.
In 2026, search operators, document platforms and AI assistants can support PDF discovery and analysis. Each serves a different purpose and has different limits.
This guide explains how to find PDFs, search their contents, process scans and verify the evidence before using it.
A PDF Research Workflow
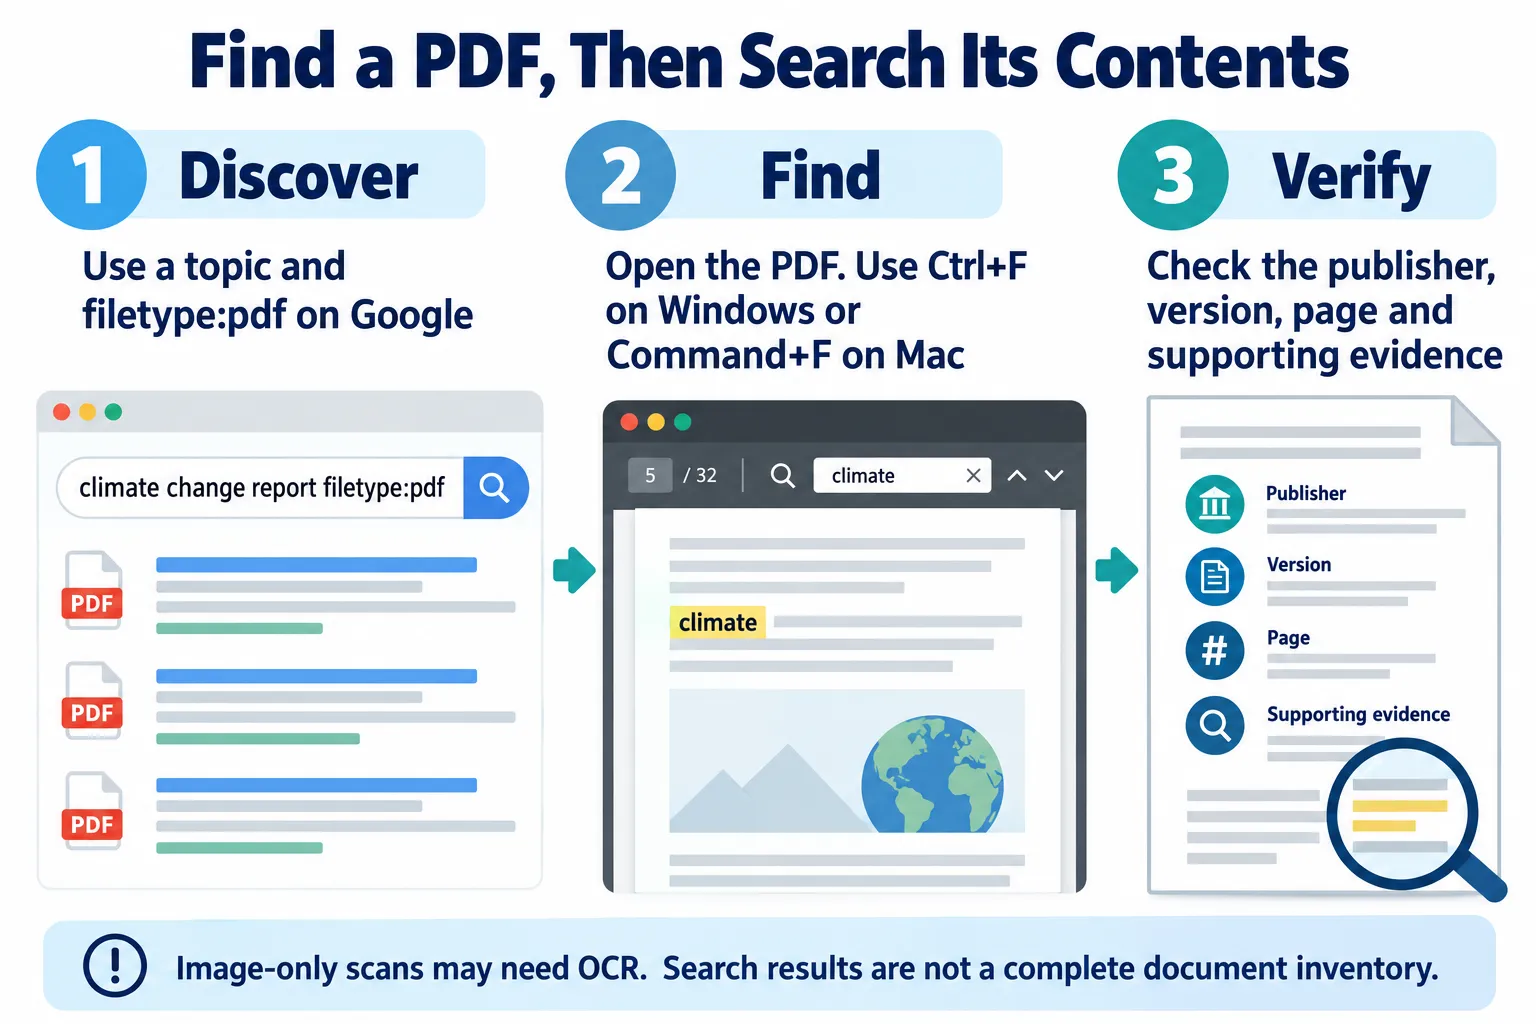
How to Search PDF Files on Google
Google supports filetype: to restrict results by file type or extension. It can help locate reports, papers, government publications and technical manuals. See Google search guidance.
Step 1: Enter your search topic
Start with a clear subject:
climate change reportStep 2: Add the PDF file type
Refine the query:
climate change report filetype:pdfThe filetype:pdf operator restricts results to files Google identifies as PDFs. It does not find every PDF on the web.
Step 3: Add an exact phrase
To narrow the results further, use quotation marks:
"climate change adaptation" filetype:pdfThis is extremely useful when you’re looking for a particular research concept, the title of a report or the name of a specific piece of literature.
Step 4: Limit the search to an organization
For example:
climate change adaptation filetype:pdf site:epa.govThe site: operator restricts results to a website or domain. That narrows discovery but does not prove authority, accuracy or completeness.
A good approach to research would be to start with a broad search, look at the terminology that the major publishers use and then progressively narrow down the search. Overly restrictive searches from the outset can have the effect of excluding potentially useful documents.
Advanced Google Search Operators for Finding PDFs
Advanced PDF search techniques incorporate standard keywords with a range of specialist operators which control the type of document, the domain of the source or the exact phrasing of the results.
Google documents filetype:, site:, exact phrases, exclusions and before:/after: filters. Treat other operators as refinements to test rather than guarantees of complete retrieval. See Google’s operator help.
Google PDF Search Operators Cheat Sheet
| Operator | Purpose | Search example | Limitation |
|---|---|---|---|
filetype: |
Find a file format | research filetype:pdf |
Only discoverable files |
| site: | Restrict a website | policy site:who.int filetype:pdf |
Not a complete site inventory |
| ” “ | Match an exact phrase | "digital literacy" filetype:pdf |
May miss alternative wording |
| – | Exclude a term | solar energy -advertising filetype:pdf |
Can exclude useful results |
| OR | Include alternatives | (policy OR framework) filetype:pdf |
Grouping should be checked |
| after: | Filter by Google’s date signals | cybersecurity after:2025 filetype:pdf |
Not proof of publication date |
| before: | Filter by Google’s date signals | privacy before:2024 filetype:pdf |
Date signals may differ |
| intitle: | Target title wording | intitle:guidelines filetype:pdf |
Not an authority filter |
| inurl: | Target URL wording | inurl:reports filetype:pdf |
URL names may be misleading |
It’s vital to be aware that ext: doesn’t work in the same way as filetype: on all search engines. For Google, filetype: is the officially supported and documented way of restricting your results by file type.
Combining search operators
A more targeted query might be:
"artificial intelligence" "education" filetype:pdf site:unesco.orgThis query asks for PDF results associated with both quoted phrases on unesco.org. Inspect the actual document and its publication record before treating it as evidence.
For broader methods, see the AI research guide.
How to Search Inside a PDF Document
The process of finding a PDF online is completely different from the process of searching within the contents of a PDF that you already have.
The vast majority of PDF readers have a Find function built in which allows you to search for text within the document you’re currently looking at.
Adobe Acrobat
- Open the PDF in Adobe Acrobat.
- Press Ctrl+F (on Windows) or Command+F (on the Mac).
- Enter the word or phrase.
- Navigate between matching occurrences.
- Use Advanced Search for more detailed searches where applicable.
Acrobat also has the facility to search across multiple PDFs and across an indexed collection of documents. See Acrobat search guidance.
Google Chrome and Microsoft Edge
Open the PDF in the browser, press Ctrl+F (or Command+F on a Mac) and type in the term you’re looking for.
The PDF viewer will highlight the matching text (provided the document has a searchable text layer rather than being image-only).
Windows and macOS
On Windows use a compatible PDF reader (such as Adobe Acrobat) or a browser PDF viewer.
On macOS simply open the PDF in Preview or some other PDF reader and use Command+F to find the text.
iPhone, iPad, and Android
Open the document in a PDF app that’s compatible with it and look for the search (magnifying glass) control.
The particular interface and the range of search options available will vary from application to application and from version of the software to version of the software.
A search with no matches does not prove the phrase is absent. Image-only pages, OCR errors, line breaks, hyphenation or unusual text encoding can cause misses. Try a shorter term and inspect the relevant pages visually.
How to Search Scanned PDFs Using OCR
An image-only scanned PDF contains page images without a searchable text layer. Some scanned files already include OCR, so first check whether you can select or find known text.
Optical Character Recognition (OCR) is used to analyze the images and extract the text into a machine-readable form so that it can be searched and extracted.
Making a scanned PDF searchable
Adobe Acrobat provides a documented workflow: Follow Adobe’s OCR instructions.
- Open the scanned document.
- Select All tools → Scan & OCR.
- Choose the file or page range.
- Set the document language.
- Select Recognize Text.
- Save the processed document.
- Search for a known phrase to check the results.
The accuracy of OCR is dependent on a number of factors including the quality of the original scan, the language of the document, the layout of the document and the general condition of the source material.
Handwritten content, degraded or faded print, complex table structures and overlapping text are all potential sources of recognition errors during the OCR process.
Before you go off and extract any numbers or quote any text it’s worth comparing the OCR text against the original scanned page to check it’s correct and faithful.
For confidential documents you must use an approved method of processing and check the privacy and retention terms prior to uploading any files to an online OCR service.
How to Search Multiple PDF Files at Once
Researchers will often be in the situation where they need to search for information across dozens or even hundreds of documents.
Searching individual files can be a very inefficient process, especially when the file names don’t in any way reflect the actual contents of the file.
Three approaches are useful.
1. Adobe Acrobat Advanced Search
Acrobat supports searching PDF collections and Acrobat Pro can create indexes for document catalogs. Very useful for research archives, legal files and technical reference libraries. See Acrobat collection search.
Some secured documents have search restrictions or may need to be searched separately. Behavior depends on permissions, the document and the Acrobat version.
2. Google Drive
Google Drive has file type filters and search options so you can find your documents within an accessible Drive collection.
Users can combine text searches with file type, owner and modified date filters. Text search results are dependent on what Drive has processed and indexed. See Drive search help.
3. Organization-wide document search
Businesses and research organizations can use document management systems with full-text indexing, OCR and permission-aware retrieval.
For image-only archives, OCR may be required before a full-text index can retrieve the content.
How to Find PDFs and Other File Types Online
Google supports indexing of a range of text and document formats, not just PDFs. See Google’s indexable formats.
| File type | Google search example | Common research use |
|---|---|---|
climate policy filetype:pdf |
Reports and papers | |
| DOCX | research protocol filetype:docx |
Editable documents |
| XLSX | economic indicators filetype:xlsx |
Spreadsheets |
| CSV | population data filetype:csv |
Structured datasets |
| PPTX | machine learning filetype:pptx |
Presentations |
| TXT | documentation filetype:txt |
Plain-text resources |
The ability to index a particular file format technically is no guarantee that Google has indexed every publicly available document of that format.
Some files will of course be inaccessible for a variety of reasons (authentication required, web crawling restrictions, no link present etc.) as part of the indexing process.
How AI Can Help Search and Analyze PDFs in 2026
AI document tools are able to answer research questions that go well beyond simple word matching.
For example, a reader might ask:
Which sections talk about the limitations of the research and what are the authors’ concerns in that regard?
Rather than just doing a standard text search, AI tools can go on to try and find the relevant passages even if the text uses different terminology or phrasing.
Practical AI-assisted PDF tasks
- Summarize lengthy reports.
- Identify the key findings and the key limitations.
- Compare documents.
- Locate relevant sections.
- Extract information into tables.
- Explain specialized terminology.
- Identify apparent contradictions.
A range of tools (ChatGPT, NotebookLM, Gemini and Adobe’s Ai-assisted PDF tools to name a few) offer various degrees of document analysis capability depending on the product you have access to and how it’s set up.
ChatGPT supports analysis of uploaded documents, including PDFs. Handling of embedded visuals varies by plan and workflow, so verify tables, charts and scanned content rather than assuming every page element was interpreted. See OpenAI upload guidance.
How to use AI responsibly
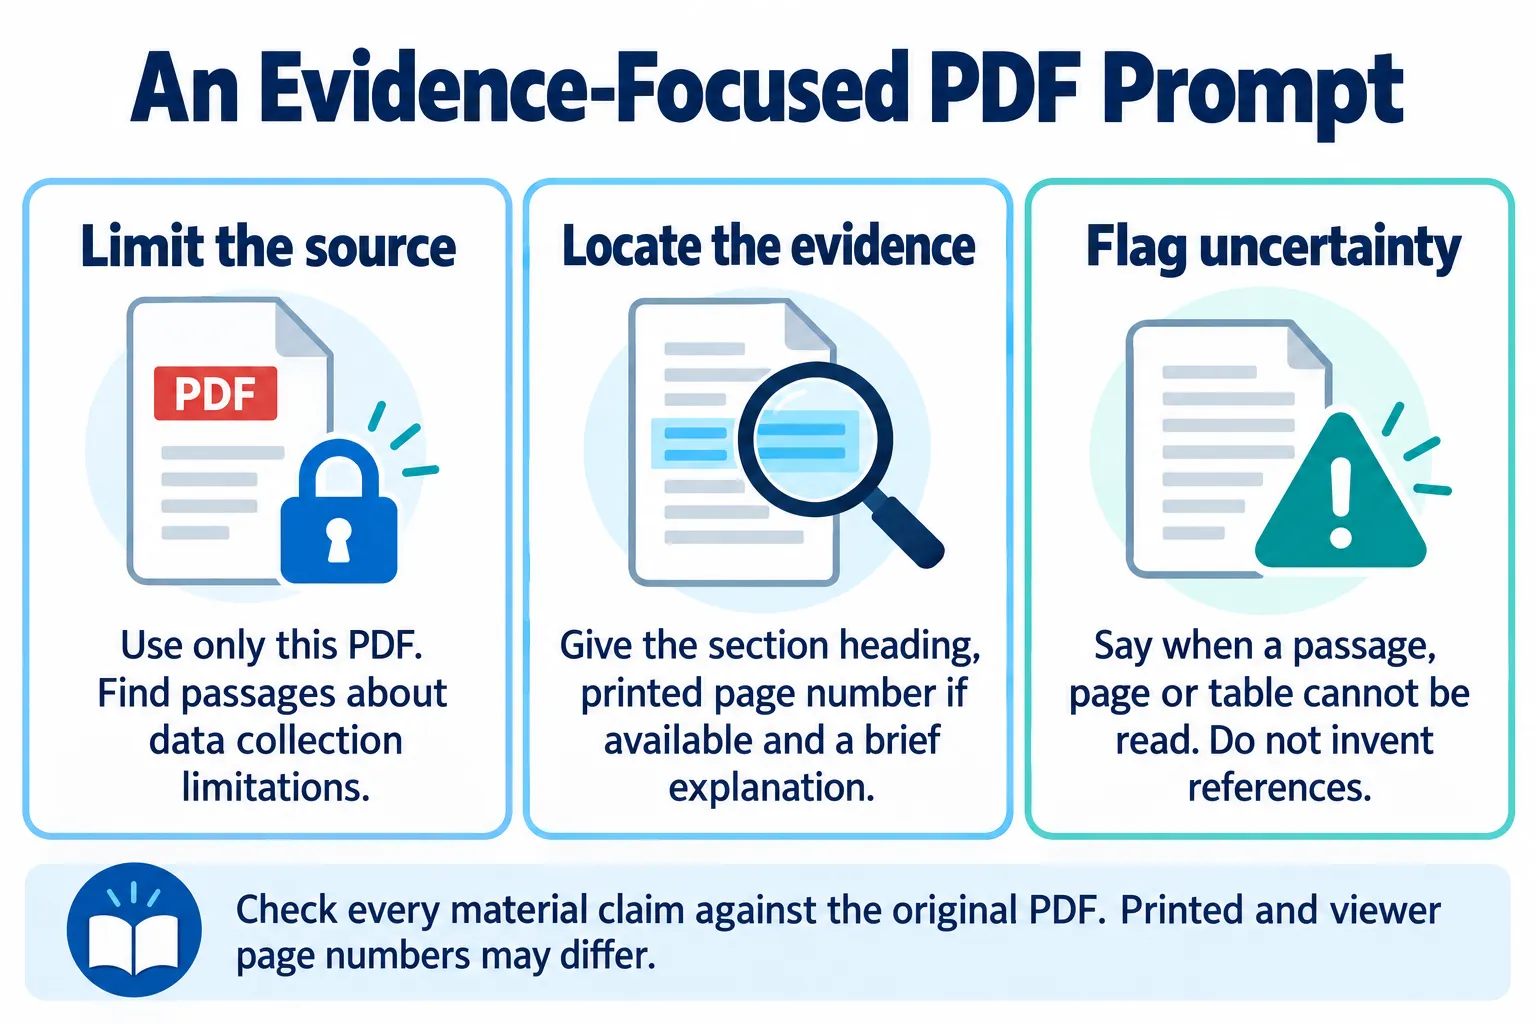
Use instructions that make evidence verification easier:
Use only this PDF. Find passages about limitations of data collection. Give the section heading, printed page number if available and a brief explanation. Flag unreadable passages or uncertain page references. Do not use outside sources or invent quotations, numbers or references.
AI may miss a section, misread a table or give an incorrect page reference. Printed page numbers can differ from the viewer’s page counter. Verify every important claim directly in the PDF.
Always verify any key conclusions against the original PDF.
Use the verification guide for checking AI-generated findings.
How Researchers Can Find Credible PDF Sources
Discovering a document is only the beginning of the research process.
A PDF from a recognizable institution may still be outdated, incomplete, superseded, or unsuitable for a particular research question.
A five-step document verification method
- Identify the publisher. Locate the official organization or repository.
- Verify authorship. Check who prepared the document and their qualifications.
- Check dates and versions. Look for publication dates, revision numbers, and updated editions.
- Examine the evidence. Review methods, references, datasets, and stated limitations.
- Confirm the original source. Compare the document with the publisher’s official listing.
For academic material, check the journal or institutional repository for publication status, corrections, or retractions.
For government information, verify that the document is the current applicable version.
Keep a source log with the document title, publisher, version, URL, access date and the page supporting each important claim.
Why PDF Search Sometimes Fails
| Problem | Recommended solution |
|---|---|
| No PDF results | Remove restrictive operators and try alternative terms |
| Text cannot be found | Check whether OCR is required |
| Outdated document | Search the publisher’s official website |
| Too many irrelevant results | Add a relevant phrase or domain restriction |
| File requires login | Use authorized access or find a public version |
| Search misses relevant files | Try another database or repository |
| Incorrect extracted text | Compare with the scanned page and rerun OCR |
Search engines are discovery tools, not complete inventories of every document published online.
Three Practical PDF Research Examples
Example 1: Find an official government publication
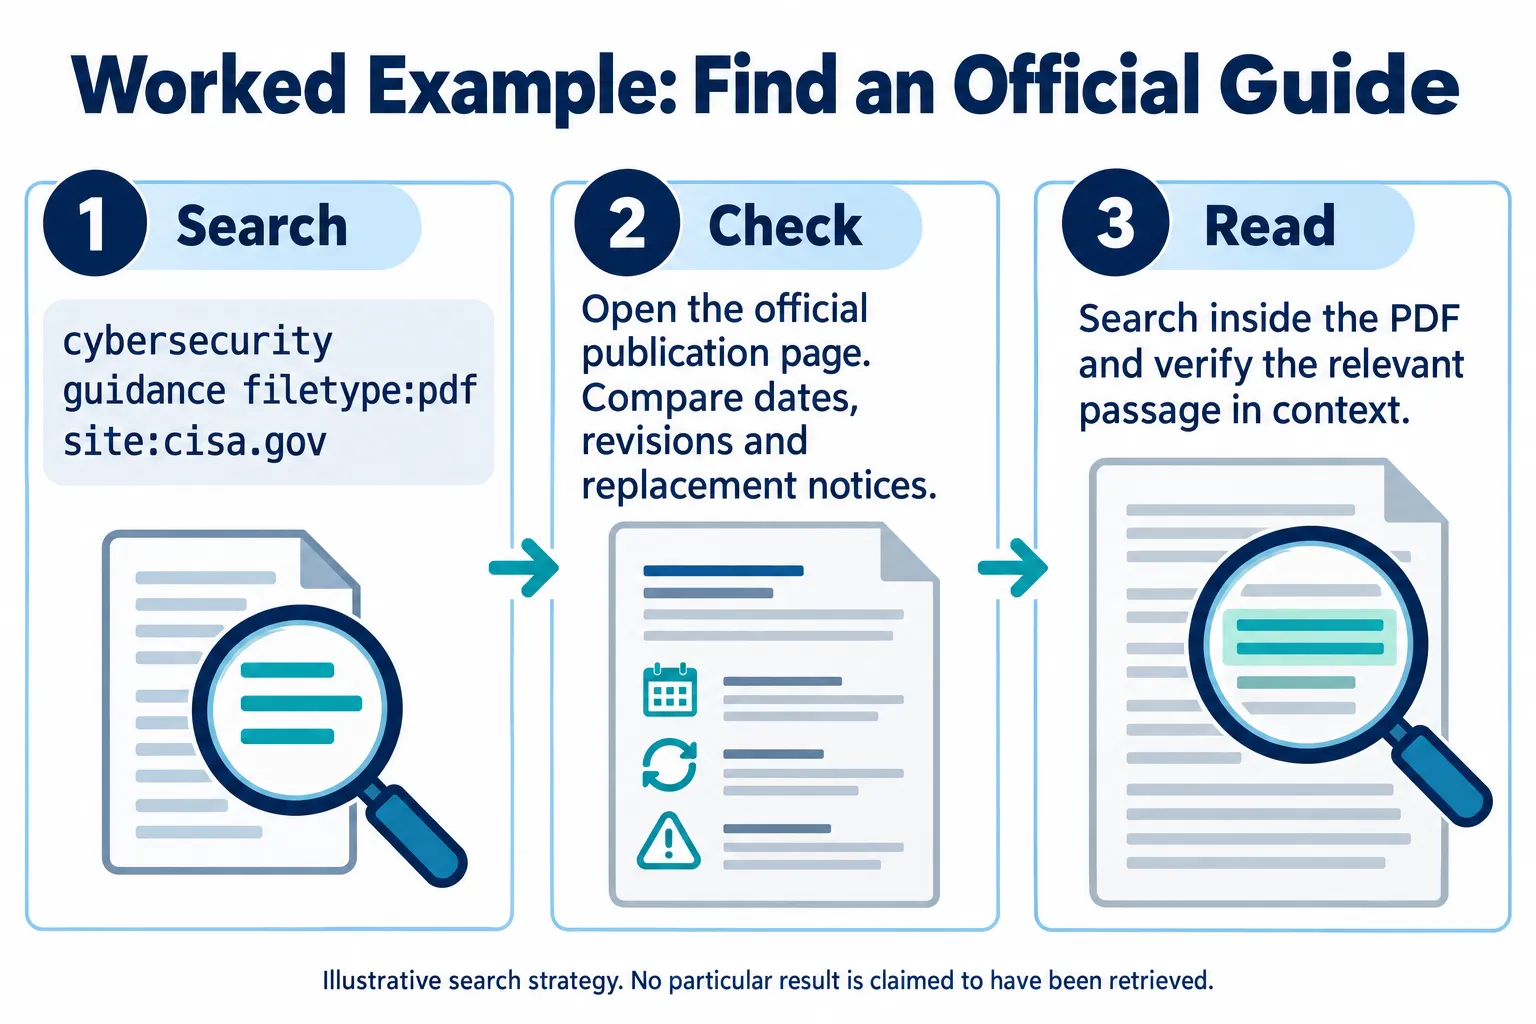
Research objective: Locate a government guide about cybersecurity.
Initial search:
cybersecurity guidance filetype:pdfRefined search:
cybersecurity guidance filetype:pdf site:cisa.govOpen the relevant government publication page, check its date, and verify whether a newer edition exists.
Example 2: Find academic research material
Research objective: Locate university publications on digital literacy.
Initial search:
digital literacy research filetype:pdfRefined search:
"digital literacy" filetype:pdf site:.eduReview the institution, authors, research methods, and publication status before using a result as evidence.
Example 3: Find a recent technical guide
Research objective: Locate an official technical guide about cloud security.
Initial search:
cloud security technical guide filetype:pdfRefined search:
"cloud security" filetype:pdf site:nist.govCheck the document identifier, release date, revision history, and official publication record.
These examples demonstrate search strategies, not claims that any particular document was retrieved.
Frequently Asked Questions About PDF Search
1. How do I search for PDF files on Google?
Enter keywords followed by filetype:pdf. For example, renewable energy report filetype:pdf narrows the results to PDF documents. Add an exact phrase or trusted domain when more precision is needed.
2. What does filetype:pdf mean?
The operator asks Google to restrict results to files identified as PDFs, using file-type information such as the HTTP content type or extension. It does not guarantee every relevant PDF will appear.
3. How do I search for a word inside a PDF?
Open the file in a compatible PDF reader and press Ctrl+F on Windows or Command+F on macOS. Enter the word or phrase and navigate through the matches.
4. Why can’t I search a scanned PDF?
An image-only PDF may lack machine-readable text. OCR can recognize the visible characters and create searchable text, although the resulting text should be checked for errors.
5. How can I make a PDF searchable?
Use a trusted OCR application, such as Adobe Acrobat’s Scan & OCR tools, to recognize the text. Save the processed document and test the search function using a phrase visible on the page.
6. Can Google search text inside PDF documents?
Google can index text extracted from supported PDF files when the documents are discoverable and accessible. Its indexed coverage is not exhaustive, particularly for restricted or image-based files.
7. How do I search multiple PDF files simultaneously?
Use a PDF reader with multi-document search, a document indexing system, or a supported cloud storage search feature. For scanned collections, OCR may be necessary before searching the text.
8. Can AI search and summarize PDFs?
Yes. Compatible AI document tools can answer questions, summarize material, and identify relevant content in uploaded PDFs. Their outputs still need verification, particularly for numbers, tables, and citations.
9. How can I find academic or government PDFs?
Combine filetype:pdf with an institutional domain. For example, digital education filetype:pdf site:unesco.org. Check the publisher and document record rather than relying only on the domain.
10. How do I find the latest version of a PDF?
Search the publisher’s official website and compare document dates, revision numbers, and replacement notices. Google date filters can help discover candidates but should not establish which version is authoritative.
Final Tips for More Effective PDF Research
Effective PDF research combines three activities: locating relevant documents, searching their contents, and evaluating the evidence. Start with a clear query, refine it with supported operators, and use OCR where necessary. AI can assist with large documents, but the underlying PDF remains the evidence that researchers must examine. Explore the advanced search guide for additional discovery methods. The strongest research method is not simply finding a PDF quickly. It is finding the right document, confirming its reliability, and recording enough information for another person to verify the result.