Not every page on a website shows up in Google, Bing, or the other big search engines. Some never get indexed. Others are blocked from crawlers. A few only appear after you fill out a form. And plenty of PDFs live inside a site’s database, visible only through its own search box.
That raises a fair research question: Can you actually find a list of public pages or PDF files that regular search results leave out?
Yes, within limits. Search operators, web archives, site search tools, XML sitemaps, and specialized document engines can surface a surprising number of hidden or hard to find public resources. Search operators query an index; they do not bypass logins, payment requirements, or other access controls. A robots.txt rule governs crawler behavior and is not itself a security barrier. Use only sources you are authorized to access.
First, Know the Difference Between “Not Found” and “Not Indexed”
A page can be missing from your search results for completely different reasons:
- It is indexed but simply doesn’t rank for the words you typed.
- It was crawled but never made it into the index.
- A robots.txt rule blocks the crawler.
- A noindex rule or an X-Robots-Tag HTTP header tells search engines not to index it.
- The page only appears after login.
- It is generated only after a form is submitted.
- It lives in a database with no public URL at all.
This distinction matters. Google’s site: operator is handy, but it is not a complete inventory of everything Google knows about a domain. Google’s own documentation says the list of URLs a site: query returns is not always exhaustive, and recommends the URL Inspection tool in Search Console when a site owner needs to check whether a specific URL can be indexed (Google site operator guide).
So when a page doesn’t appear in Google, don’t assume it doesn’t exist. It may just sit outside the part of the web that search engines can freely crawl and index.
Get the Search Query Format Right
A common mistake is mixing up the operators. This query is incorrect:
filetype:aofirs.org inurl:"contact"
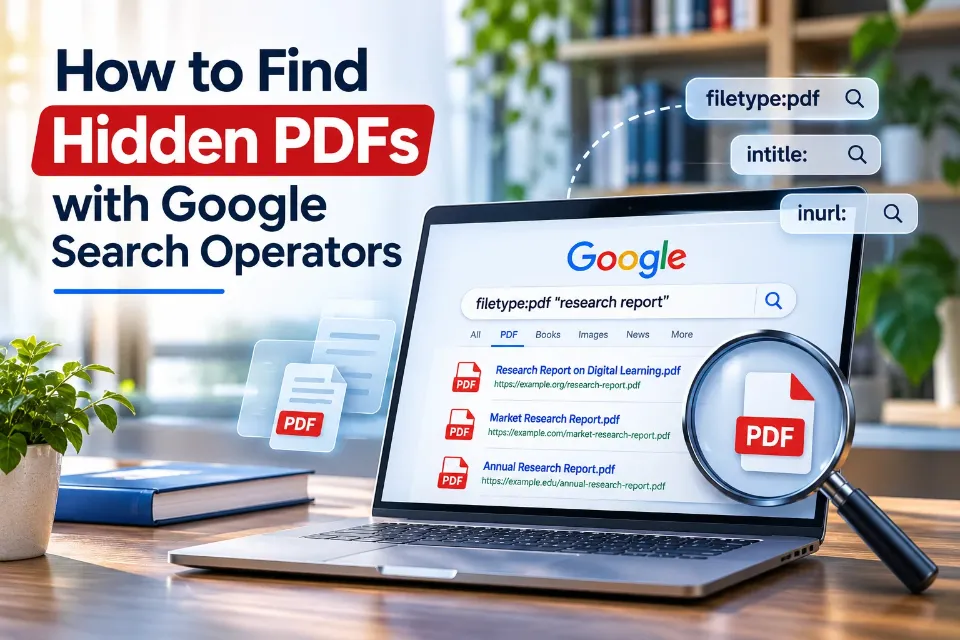
The filetype: operator filters file types, such as PDF, DOCX, PPT, XLS, or TXT; it is not a domain filter. Google can identify a file type from its content type or file extension. A better version looks like this:
site:aofirs.org inurl:contact
And for PDFs on the same domain:
site:aofirs.org filetype:pdf
Google supports site: to limit results to a domain and filetype: to hunt for specific document types, and its help page warns that there must be no space after the colon (Google search refinement). Getting the order and purpose of each operator right makes a big difference.
Can Search Operators Reach Pages That Appear After a Contact Form?
Usually, no.
Pages that only show up after you submit a contact form are often not ordinary public pages. They might be:
- A thank you page that isn’t linked from anywhere else on the site
- A POST response generated only after the form is sent
- A CRM or email automation endpoint
- A page blocked by a noindex tag
- Something protected by login, cookies, sessions, CAPTCHA, or CSRF tokens
- A redirect URL that only appears after a valid form action
Search engines mainly discover content by following links and crawling URLs. If there is no crawlable public URL, or if the URL only appears after a POST form submission, a normal search query almost never reaches it. Researchers who study “hidden databases” have pointed this out for years: engineers at Google described the deep web as content behind HTML forms, which crawlers that rely on hyperlinks generally cannot reach without submitting the form with valid inputs (Google deep-web crawl study). That has historically kept such content out of general search engine indexes.
If the thank you page is public and indexed, you might still find it with queries like:
site:example.com inurl:thanksite:example.com inurl:thankssite:example.com inurl:successsite:example.com inurl:confirmationsite:example.com intitle:"thank you"site:example.com "thank you for contacting"
But if the page isn’t indexed, isn’t linked, is blocked, or is generated only after submission, Google search operators will not reliably expose its content. A robots-blocked URL may still be listed if Google discovers links to it, but that does not grant access to protected content.
Can We Find Pages That Prevent Indexing?
Sometimes, but only partially.
Pages can stop themselves from being indexed with a meta robots tag such as:
<meta name="robots" content="noindex">
For non-HTML files like PDFs, site owners can use the X-Robots-Tag HTTP header; Google’s specification names it as the way to block indexing of non-HTML resources such as PDF, video and image files (Google robots specifications). There is a catch, though: if a URL is already blocked in robots.txt, Google never crawls the page and therefore never sees the noindex rule, so the URL can still appear in results if other pages link to it (Google noindex guidance).
From the outside, you can look for clues, but you cannot pull a complete list of every noindexed page on someone else’s site. If you own the site, the right tools are:
- Google Search Console Page Indexing report
- Google Search Console Crawl Stats report
- URL Inspection tool
- XML sitemap files
- CMS media library
- Server logs
- Database exports
- Crawling tools such as Screaming Frog, Sitebulb, or JetOctopus
Google’s Page indexing report shows which of a site’s URLs Google has indexed and which it has not, grouped by reason, including “URL blocked by robots.txt” and “URL marked ‘noindex'” (Page indexing report).
How to Find Public PDFs on a Website
Start simple:
site:example.com filetype:pdf
Then expand with common URL patterns:
site:example.com filetype:pdf inurl:uploadssite:example.com filetype:pdf inurl:documentssite:example.com filetype:pdf inurl:resourcessite:example.com filetype:pdf inurl:filessite:example.com filetype:pdf "report"site:example.com filetype:pdf "white paper"site:example.com filetype:pdf "guide"site:example.com filetype:pdf "certificate"
For WordPress sites, try:
site:example.com filetype:pdf inurl:wp-content/uploads
On education, nonprofit, or research sites, these often work well:
site:example.com filetype:pdf "annual report"site:example.com filetype:pdf "policy"site:example.com filetype:pdf "training"site:example.com filetype:pdf "curriculum"site:example.com filetype:pdf "research"
These queries search Google’s index, so they cannot inventory unindexed PDFs. A result may also be stale or refer to a URL whose current access permissions have changed. Google lists PDF among the file types it can index, alongside Word, Excel, PowerPoint, OpenDocument, EPUB, RTF and plain-text formats (Google indexable file types).
For more PDF-specific techniques, see the AOFIRS guide on search PDF files. For the wider picture of content that search engines cannot index, see search the invisible web.
Does Google Actually Read the Text Inside PDF Files?
Yes, when the PDF is publicly accessible and text-based.
Google can index the content of many text-based file formats, including PDFs (Google indexable file types). That means a search query can match words that appear inside an indexed PDF, not just in the file name or URL. For example:
site:example.com filetype:pdf "business credit underwriting"
The search engine is not reading the website’s private database live. It is searching its own index. If the PDF has never been crawled, is blocked, requires login, is generated after a private search, or exists only as a database record without a public URL, Google will not normally find it.
Scanned PDFs are harder. Google’s file-type documentation says encoded formats such as PDF need a parser to extract the human-readable text, and it does not say how image-only scans are handled (Google indexable file types). Treat a scan with no text layer as possibly unsearchable by keyword. Some archives run OCR themselves: the Internet Archive’s full-text search uses OCR text derived from uploaded PDFs and scanned images (Internet Archive search guide).
Can You Find PDFs Stored Inside a Website Database?
Sometimes, but not always.
A PDF sitting in a database can be found only if the website exposes it through a public URL, a public search result, a public download link, a sitemap, an API, or an indexed document page. For example, a PDF may live in a database yet still be served through a URL like:
/download?id=1234
or
/resources/report-name.pdf
If that URL is public and crawlable, search engines may index it. But if the PDF is available only after login, payment, form submission, internal site search, role based permission, a session based download, a private database query, CAPTCHA, or a temporary signed URL, normal search engines usually cannot reach it.
A useful rule of thumb: Search engines do not index databases. They index URLs. If the database content is turned into crawlable public URLs, search engines can discover it. If the content stays inside the database with no public URL, it remains part of the deep web.
Use the Website’s Own Search Tool
Some website databases expose documents through the site’s internal search even when Google does not show them. Try searching the website itself for terms such as:
- report
- guide
- document
- download
- file
- archive
- policy
- white paper
- case study
- certificate
- form
- application
If the site search produces public result URLs, inspect whether those result pages are crawlable. Result pages that use normal GET URLs (for example, /search?q=report) are easier to revisit and research. If the site search relies on POST requests, sessions, or JavaScript only results, search engines may not be able to index those results.
Check Sitemaps and Public Index Files
Many websites expose public sitemaps. These can reveal pages and files that never appear in everyday search results. Try these common locations:
/sitemap.xml/sitemap_index.xml/wp-sitemap.xml/post-sitemap.xml/page-sitemap.xml/attachment-sitemap.xml
Some WordPress plugins publish attachment or media sitemaps; availability depends on configuration. WordPress does not universally expose every uploaded PDF through an attachment sitemap. You can also search for sitemap URLs in Google:
site:example.com inurl:sitemap
Sitemaps are especially useful because they show what the site owner has chosen to expose to crawlers. They still will not reveal private database files that are not listed.
Use Web Archives Carefully
The Internet Archive can help locate old pages and files that were once public. Its Wayback Machine is searched mainly by address: you enter a domain or URL and browse the dated captures, optionally within a date range (Wayback Machine guide). It is not a full-text search engine for archived web pages. As of November 2026, its help page says full-text search of archived sites is not available and describes it only as something the Archive hopes to add; check the page for the current position before relying on this.
For PDFs, list everything the Wayback Machine holds for a site with the wildcard address the help page gives for that purpose, then look through the list for addresses ending in .pdf:
web.archive.org/*/example.com/*
This may reveal PDFs that were once public and archived. It will not reveal PDFs that were never exposed as public URLs. Archive.org’s main search covers item metadata such as titles, creators and descriptions, and a separate full-text search looks inside uploaded books and other texts using OCR-derived text (Internet Archive search guide).
Specialized Search Engines for PDFs and Deep Web Documents
There is no universal search engine that can walk into every website database and pull out hidden PDFs. But several specialized tools help with public or semi-structured document discovery.
| Tool | Best For |
|---|---|
| Google and Bing | General public PDFs. Use site:example.com filetype:pdf and variations with keywords or inurl:download. |
| Internet Archive / Wayback Machine | Older public URLs, removed pages, archived PDFs and historic website versions, especially useful when a PDF once existed publicly but was later taken down (Wayback Machine guide). |
| CORE | Open-access academic papers aggregated from repositories and journals; CORE describes itself as the largest collection of open-access full texts and reports more than 40 million full-text documents available for machine access (About CORE). |
| BASE | Academic repositories, theses, open-access documents and institutional materials. Operated by Bielefeld University Library; its content-provider page listed about 394 million documents from more than 11,000 providers at its last update in April 2024 (BASE content providers). |
| Google Scholar, Semantic Scholar, PubMed Central, ResearchGate | Scholarly papers, white papers, citations and author-uploaded PDFs. Useful for academic discovery, but they do not crawl arbitrary private website databases. |
Practical Research Workflow
When you need to find pages or PDFs that are missing from normal search results, follow this sequence. The flowchart below gives a quick visual overview.
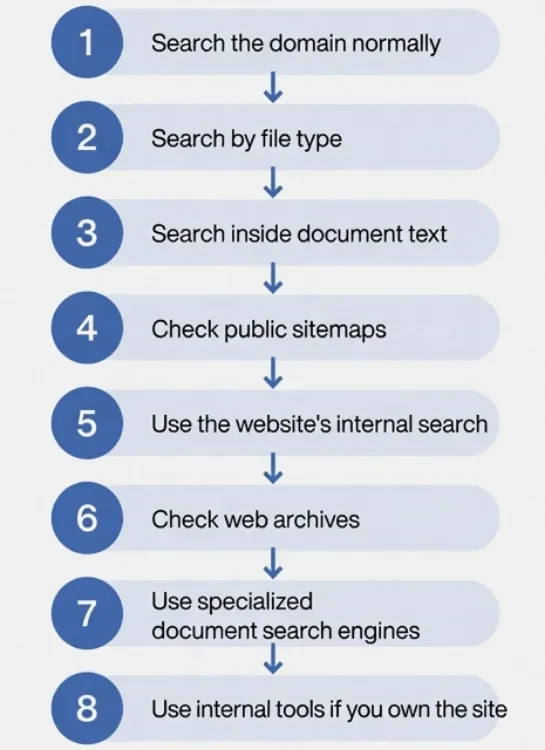
Step by step checklist
- Search the domain normally. Start with site:example.com, then add inurl:contact, inurl:thank, inurl:download, or inurl:resources.
- Search by file type. Use site:example.com filetype:pdf (also try docx, pptx, xlsx).
- Search inside document text. Add an exact phrase: site:example.com filetype:pdf “annual report”.
- Check public sitemaps. Look for XML sitemaps, attachment sitemaps, and document sitemaps.
- Use the website’s internal search. Search the site itself for document related terms.
- Check web archives. Use the Wayback Machine for old versions of pages or historic PDF URLs.
- Use specialized document search engines. Try CORE, BASE, Google Scholar, Semantic Scholar, or the Internet Archive, depending on the topic.
- If you own the site, use internal tools. Search Console, server logs, the CMS media library, database exports, and authenticated crawlers. Use authorized internal inventories to investigate private, noindexed, or database-only assets. Each tool has coverage limits; reconcile the CMS, storage, database, logs, and crawl results instead of treating one list as complete.
Ethical and Legal Boundary
Finding public pages is legitimate research. Bypassing access controls is not.
Do not try to access password protected files, private user data, paid materials, admin areas, form only endpoints, or files that clearly are not intended for public access. If a document appears to be sensitive, confidential, or accidentally exposed, do not download, redistribute, or exploit it. Report it responsibly to the website owner.
Conclusion
Yes, you can find many pages and PDFs that do not appear in normal search results, but only if they are publicly accessible somewhere. Search operators can surface indexed PDFs and public URLs. Web archives can reveal old public files. An internal site search may expose database-backed resources. Specialized engines such as CORE and BASE can locate academic PDFs from repositories and open access sources.
Search queries do not bypass access controls or directly expose private database files. Public form results, formerly indexed URLs, and robots-blocked URLs can sometimes be discovered, but discovery is not permission to access protected material. Search engines do not search private website databases directly. They search their own indexes of URLs they were able to crawl, process, and store. The shortest useful formula is this: If it has a public URL and can be crawled, it can often be found. If it only exists inside a private database, behind a form, or behind access control, search operators will not reach it.
References
- Bielefeld University Library. (2024). Content providers. BASE (Bielefeld Academic Search Engine). Retrieved November 4, 2026, from BASE content providers.
- CORE. About CORE. Retrieved November 4, 2026, from About CORE.
- Google. Page indexing report. Search Console Help. Retrieved November 4, 2026, from Page indexing report.
- Google. Refine Google searches. Google Search Help. Retrieved November 4, 2026, from Google search refinement.
- Google Search Central. (2025a, December 10). site: search operator. Google for Developers. Google site operator guide.
- Google Search Central. (2025b, December 10). Block search indexing with noindex. Google for Developers. Google noindex guidance.
- Google Search Central. (2026a, March 24). Robots meta tag, data-nosnippet, and X-Robots-Tag specifications. Google for Developers. Google robots specifications.
- Google Search Central. (2026b, February 3). File types indexable by Google. Google for Developers. Google indexable file types.
- Internet Archive. Using the Wayback Machine. Internet Archive Help Center. Retrieved November 4, 2026, from Wayback Machine guide.
- Internet Archive. Search: A basic guide. Internet Archive Help Center. Retrieved November 4, 2026, from Internet Archive search guide.
- Madhavan, J., Ko, D., Kot, Ł., Ganapathy, V., Rasmussen, A., & Halevy, A. (2008). Google’s deep-web crawl. Proceedings of the VLDB Endowment, 1. Google deep-web crawl study.